Category: History

  • How Ceefax Died and the BBC Tried to Replace It: The Digital Transition Nobody Quite Got Right

    How Ceefax Died and the BBC Tried to Replace It: The Digital Transition Nobody Quite Got Right

    On 23 October 2012, at 23:32, the last Ceefax page was transmitted. It was page 100, the index, going dark on the analogue signal as the London region completed the final stage of the UK’s digital television switchover. A service that had been running since 1974 simply stopped. No farewell gala, no prime-time documentary. Just a blank where the chunky pixel text had been for nearly four decades. I’ve always found something poetic in that quietness. Ceefax didn’t get a send-off worthy of what it actually was: the world’s first public teletext service, and for millions of British households, the default way of knowing things.

    What followed the ceefax digital switchover was a genuine institutional puzzle. The BBC had spent years preparing for a post-analogue world, building websites, launching the Red Button service, and investing in what it called “connected TV”. But Ceefax’s audience was not the kind that moved quietly from one platform to another. They were loyal in the particular way that practical tools earn loyalty. You didn’t love Ceefax. You just used it, constantly, and only noticed it was gone once it was.
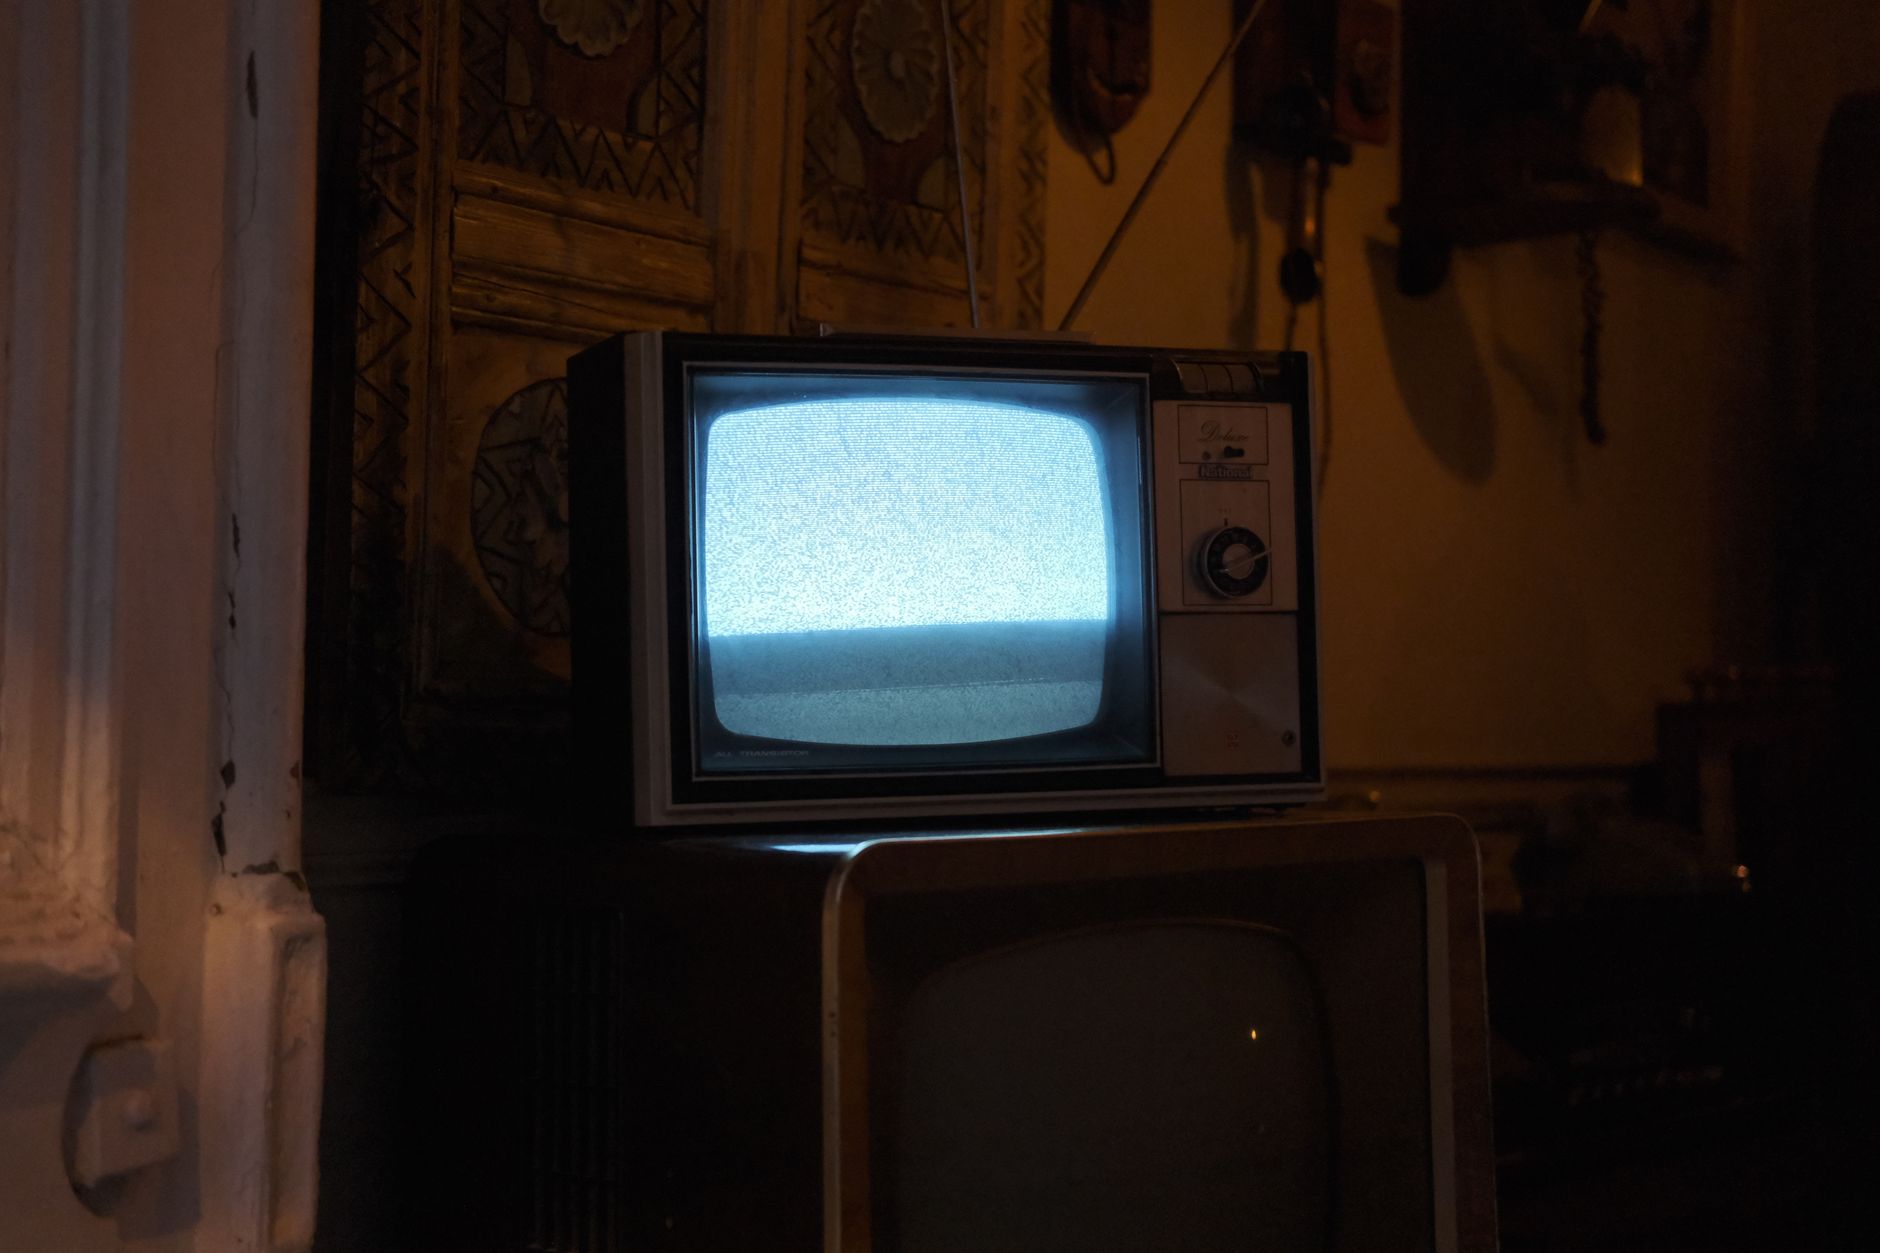
    Vintage CRT television displaying teletext, representing ceefax digital switchover history uk
    Photo by Deniz Karbaş on Pexels

    What Ceefax actually was, and why it mattered so much

    Ceefax launched in September 1974, born from BBC engineer John Forrest’s experiments with using spare bandwidth in the television signal to carry text data. The name came from “see facts”. By the early 1990s it had around 20 million regular users in the UK, a figure that would embarrass most websites of the period. Pages were updated continuously by a small editorial team in London; the weather, football scores, news headlines, TV listings, and travel information refreshed in a rolling cycle that viewers learned to read by feel. Page 302 was sports news. Page 417 was the football scores. People knew these numbers the way they knew their own postcodes.

    The technology was elegantly simple. Data rode piggyback on the analogue television signal in the vertical blanking interval, those black lines at the top of the picture. A decoder in the television set grabbed the relevant page when requested and held it on screen. No internet connection required. No login. No latency beyond the wait for your page to cycle round, which could be 20 or 30 seconds on a busy news day. That wait, maddening in retrospect, was also part of the ritual. You sat with it.

    The Red Button: the BBC’s first answer to the switchover

    Digital television, in the form of Sky and then Freeview, had been available since the late 1990s. The BBC’s response was to build a digital teletext equivalent accessed via the red button on the remote. Technically it was a step forward: more pages, more colours, photographs on some sections. But the complaints from Ceefax loyalists were immediate and consistent. The Red Button service was slower. It required navigating menus rather than typing a known page number. The sports scores section, always Ceefax’s crown jewel during Saturday afternoons, felt clunkier to browse. And the aesthetic shift, away from the grid of text toward something trying to look like a website on your television, struck many users as a solution to a problem nobody had raised.

    I’d argue that the Red Button’s designers were caught between two audiences. They were trying to serve Ceefax veterans while also appealing to a younger demographic who had grown up with the web. The result pleased neither group fully. Web users found it primitive. Ceefax users found it unnecessarily complicated.

    BBC Online and the assumption that the web would absorb everything

    Alongside the Red Button, the BBC’s broader digital strategy assumed that bbc.co.uk would absorb the functions Ceefax had served. By 2012, BBC Online was one of the most-visited websites in the country, and the news, weather, and sport sections were genuinely excellent. The weather pages in particular had benefited from Met Office data integration that Ceefax’s pixel graphics could never have matched.

    But the web required a device. A broadband connection. A screen separate from the television. For the demographic that had relied most heavily on Ceefax, typically older viewers, those hurdles were real. The BBC’s own retrospective coverage acknowledged that Ceefax had been particularly important for users with limited mobility or visual impairments, for whom the simplicity of the page-number system was an accessibility feature that no web interface had fully replicated.

    There’s a broader point here about what the ceefax digital switchover history in the UK reveals about public broadcasting’s relationship with the web. The BBC was, in many ways, ahead of most institutions in going digital. Its online archive projects, the iPlayer launch in 2007, the investment in digital journalism were all serious efforts. But the web the BBC built was web-shaped: scrolling, clicking, linking, searching. Ceefax was television-shaped: passive, navigable by number, requiring no literacy in hyperlinks or search queries. Those are genuinely different things, and the transition treated the first as an upgrade when for some users it was simply a different tool.

    What the scores page meant on a Saturday afternoon

    It is hard to overstate the cultural weight of page 302 and its descendants on a Saturday at around five o’clock. Before the proliferation of rolling sports news channels and live score apps, Ceefax was where you went when the radio wasn’t to hand. The football results updated in near-real time. Hundreds of thousands of people would sit watching a page cycle, waiting for the score from Filbert Street or Elland Road to appear. The ritual is described in enough memoirs and think pieces that it qualifies as a shared national memory, which is a strange thing to say about a text service on a television.

    The BBC’s Sport website eventually matched and exceeded Ceefax for live scores. The app, launched properly in the early 2010s, put score updates in your pocket in real time. But the television, the shared family screen in the corner of the room, lost its function as the household oracle. That shift happened quietly alongside the ceefax digital switchover and deserves its own acknowledgement. It wasn’t just a technology change. It was a redistribution of how information entered the home.

    This connects to a theme running through the broader history of early British digital services. The transition from print classified ads to online equivalents produced the same pattern: a service that felt indispensable, a digital replacement that was technically superior but socially different, and a period of genuine loss that the technology industry rarely admitted to.

    Why nothing has quite replaced it

    In 2026, the BBC Red Button still exists. It has been refined considerably since 2012, and its news and weather sections are competent. Smart televisions mean that some of the friction of accessing BBC Online from the living room has reduced. But the Ceefax model, a single universal service accessed by any television in the country with no account, no algorithm, no personalisation, is not something the contemporary web can recreate without someone deciding that it is worth recreating. Nobody has made that decision.

    What Ceefax represented was a kind of radical equality of access. The same page 100 appeared on a television in Kensington and a television in Grimsby. There was no version of Ceefax that showed you sport because you’d previously looked at sport. The editorial team made choices about what was on each page, and those choices were universal. That’s an unusual thing in 2026, when almost every information service delivered through a screen is shaped by what the platform thinks you want to see.

    The transition period for British institutions going digital was rarely clean. Banks, councils, broadcasters: all of them found that the web was a different medium with different assumptions, and that translating a beloved analogue service into a digital one was never simply a matter of moving the content across. Ceefax is perhaps the clearest example because its replacement was so visible, and because the gap it left was felt so immediately by so many people. The digital switchover was technically complete on that October night in 2012. The cultural switchover took considerably longer, and I’m not convinced it is finished yet.

    The story of how early web portals tried to become the home page of British internet life is in some ways the same story told from the other direction. The web was reaching toward the television audience at the same moment Ceefax was being switched off, and for a few years in the late 1990s and early 2000s, neither side was quite sure who would win. The answer, in the end, was that both lost something.

    Frequently Asked Questions

    When was Ceefax switched off in the UK?

    The last Ceefax signal was transmitted on 23 October 2012 at 23:32, when the London analogue television region completed the UK’s digital switchover. Regional services had been going dark in sequence from October 2007 as different parts of the country completed their switchover.

    What replaced Ceefax after the digital switchover?

    The BBC’s primary replacement was its Red Button service, accessible via digital television on Freeview, Sky, and Virgin Media. BBC Online (bbc.co.uk) and the BBC News and Sport apps were also positioned as digital equivalents, though none replicated the simple page-number navigation system that Ceefax had used.

    Why did people find Ceefax so hard to replace?

    Ceefax required no internet connection, no login, and no separate device beyond the television itself. Its page-number system was memorised by regular users, making it extremely fast to navigate. Digital replacements required broadband connections, new devices, or navigating multi-level menus, which represented a genuine barrier for older and less technically confident users.

    How many people used Ceefax at its peak?

    At its peak in the early 1990s, Ceefax had an estimated 20 million regular users in the UK. It was particularly popular for football scores, weather forecasts, news headlines, and television listings, serving as many households’ primary source of quick factual information before the internet became widespread.

    Does the BBC Red Button still exist in 2026?

    Yes, the BBC Red Button service continues to operate in 2026 on digital television platforms including Freeview, Sky, and Virgin Media. It provides news, weather, sport, and TV listings, though its audience is considerably smaller than Ceefax’s peak figures and it competes with a range of streaming and app-based alternatives.
  • The Story of Ananova: How a Yorkshire News Agency Built the World’s First Virtual Newscaster

    The Story of Ananova: How a Yorkshire News Agency Built the World’s First Virtual Newscaster

    There is a moment in the spring of 2000 that I keep returning to whenever someone asks me what early internet optimism actually looked like in practice. Press Association, the venerable national news agency founded in 1868, unveiled a green-haired computer-generated woman who could read the news. Her name was Ananova. She had no voice actor. She had no autocue. She was rendered in real time by software running on servers in Leeds, and the world treated her like a glimpse of the future. She was, in a very specific sense, the world’s first virtual newscaster, and almost nobody under thirty has heard of her today.

    CGI news character on a monitor representing the Ananova virtual newscaster history UK
    Photo by Steve A Johnson on Pexels

    That gap between the intensity of her launch and the completeness of her disappearance is exactly the kind of story this site exists to tell. The Ananova virtual newscaster history UK chapters are brief, peculiar and worth taking seriously, because they capture something essential about the year 2000 internet: the conviction that automation, personality and always-on news delivery would combine into something genuinely new. In most respects, the people who built Ananova were right. They were simply about fifteen years too early.

    Where Ananova came from: PA Media’s digital gamble

    Press Association had been distributing news copy to newspapers, broadcasters and wire subscribers since the Victorian era. By the late 1990s, its executives could see that the web was going to do something uncomfortable to that model. Text feeds sent to newsrooms were one thing; the internet was becoming a destination in itself, and PA needed to be on it rather than merely supplying it.

    The solution was a separate digital subsidiary called PA New Media, operating out of Leeds. The team there were tasked with building an online news portal, but the question was how to make it stand out. Text-and-links news sites were already everywhere by 1999. Video required bandwidth that dial-up Britain simply did not have. The answer the team arrived at was a character: a CGI newsreader who could be generated cheaply, updated continuously and delivered in small, bandwidth-friendly files. She would read headlines to you. She would be personalised. She would feel, at least in theory, like a television presenter living inside your browser.

    The technical work was handled in collaboration with a company called Illumina Digital, and the result was Ananova, named after the Latin word for news. Her appearance was designed deliberately to be friendly rather than uncanny: green hair (to distinguish her clearly from any real person), a round face, large eyes. She spoke in a synthesised voice that was recognisably British, if somewhat mechanical. When she launched publicly on 19 April 2000, the BBC, Sky News and newspapers across Europe covered the story. The PA Media press release claimed she was the world’s first photorealistic virtual newscaster, and nobody seriously disputed it.

    What Ananova actually did, and how she worked

    The technical architecture behind Ananova was more interesting than most of the coverage acknowledged at the time. The system pulled live news copy from the PA wire feed, ran it through a text-to-speech engine, and then used facial animation software to synchronise Ananova’s lip movements and expressions to the audio. The whole process was largely automated. A human editor could intervene to prioritise stories or adjust the queue, but in theory the machine could run without one.

    Users visiting the Ananova website would see her appear in a small video window, delivering short bulletins on the top stories of the moment. The site also offered standard text news, but the character was the draw. You could customise which topics she covered. You could ask her to focus on sport, technology or business. The personalisation angle was heavily marketed, and in 2000 it felt genuinely novel. This was, after all, the year that most British households were still connecting via dial-up; the idea that your computer could generate a tailored news broadcast on demand seemed remarkable.

    I’d argue the personalisation element was actually more historically significant than the CGI face. What Ananova was attempting algorithmically, in a crude way, was something that Twitter, Google News and TikTok’s For You page would later make universal. She was a very early stab at a filtered, automated, personality-driven information feed. The character was the wrapper; the underlying logic was the real innovation.

    The Ananova website also carried standard news articles, sport, entertainment and weather alongside the video bulletins. It was, in effect, a full portal in the style of the period, comparable in ambition to what was happening at other British digital ventures of the era. If you want a sense of what that portal landscape looked like, the story of LineOne, the BT and News International portal, covers similar territory from a different angle. The difference with Ananova was the character at the centre of it, which gave it a marketing hook none of the other portals could match.

    The Orange acquisition and the beginning of the end

    Ananova launched into a media environment that was about to change sharply. The dot-com crash of 2000 and 2001 was already building when she debuted in April; by the summer, the mood in technology investment had darkened considerably. PA New Media needed a buyer, and it found one quickly. Orange, the mobile network operator, acquired Ananova Limited in May 2000 for approximately £95 million. The speed of the deal was striking; the launch had been in April, and within weeks the company had been sold.

    Orange’s logic was coherent at the time. Mobile internet, delivered through WAP and the nascent 3G networks, was supposed to be the next battleground. A customisable, automated news service delivered by a CGI character seemed like exactly the kind of content that would work on a small screen. Orange rebranded the service slightly and integrated Ananova into its mobile offering. For a period, she appeared on Orange handsets delivering short news clips.

    The problem was that WAP was a disaster, 3G was years away from being practical in Britain, and the kind of fluid video experience that made Ananova interesting on a desktop was essentially impossible on a mobile phone in 2001. The character continued to exist, the website continued to run, but the energy behind it dissipated. Staffing was cut. Development slowed. The green-haired newsreader who had generated global headlines became a minor feature of an Orange web portal rather than the centrepiece of a media revolution.

    What Ananova’s disappearance tells us

    Orange eventually sold the Ananova news portal assets to PA Group in 2009, by which point the site had become a fairly standard celebrity and entertainment news aggregator, the CGI newsreader long since retired. The domain continued to operate for several more years as a lightweight entertainment portal before being quietly discontinued. The character herself has no active presence anywhere; she exists now in archived screenshots, a handful of YouTube clips uploaded from old recordings, and the memories of anyone who happened to visit the site in 2000.

    The Ananova virtual newscaster history UK story sits alongside several other British internet ventures of the same period that captured extraordinary attention and then evaporated, often through a combination of timing, acquisition and strategic drift. The ambition that produced her was genuine. The team in Leeds built something technically coherent and culturally interesting. What finished her was not a failure of imagination but a failure of infrastructure: the internet of 2000 could not deliver what she promised, and by the time it could, the concept had been absorbed into a dozen other formats without anyone noticing.

    She has something in common with other forgotten experiments from that period. Last.fm, built in London, had a similarly ambitious vision for personalised media that took years to find its moment. The automated, personality-driven news feed that Ananova sketched out in 2000 is now so ordinary that we barely register it. Every news app on your phone is, in some sense, her descendant. She just did not survive long enough to see it.

    The PA wire that supplied her stories is still running. The agency founded in 1868 continues to distribute copy to British newsrooms. Ananova, the green-haired newsreader generated in real time from a server in West Yorkshire, lasted less than a decade in any meaningful form. She was built at the exact point where ambition and bandwidth diverged, and the bandwidth won.

    Frequently Asked Questions

    What was Ananova and when did she launch?

    Ananova was a computer-generated virtual newsreader created by PA New Media, a digital subsidiary of Press Association, and launched publicly on 19 April 2000. She used text-to-speech and facial animation software to deliver automated news bulletins via a website, and was widely described as the world’s first photorealistic virtual newscaster.

    Who built Ananova and where was she made?

    Ananova was developed by PA New Media, part of the Press Association group, working out of Leeds. The technical development involved a company called Illumina Digital, which handled the CGI character rendering and animation systems that allowed her to lip-sync to synthesised speech in near real time.

    Why did Orange buy Ananova and how much did they pay?

    Orange acquired Ananova Limited in May 2000 for approximately £95 million, just weeks after the public launch. The mobile network believed that a customisable, automated CGI news service would work well on WAP and the forthcoming 3G mobile internet, though the limitations of early mobile technology meant the vision never fully materialised.

    What happened to Ananova after Orange bought her?

    Orange integrated Ananova into its mobile and web services, but the CGI newsreader element gradually disappeared as investment was cut and the technology failed to scale to mobile. Orange eventually sold the Ananova news portal assets back to PA Group in 2009, by which point the site had become a standard celebrity news aggregator with no virtual presenter.

  • Before Spotify: How Last.fm Was Built in London and Changed the Way the World Listened to Music Online

    Before Spotify: How Last.fm Was Built in London and Changed the Way the World Listened to Music Online

    There is a particular kind of grief that comes with watching something you loved quietly fade. Last.fm never vanished with a bang. There was no dramatic shutdown announcement, no final blog post mourning its own passing. It just gradually became less of what it once was, which in some ways is a sadder ending. I’ve spent considerable time with the Wayback Machine exploring what Last.fm looked like at its peak, and the archaeology of it is genuinely startling. Here was a London-born platform that had solved the problem of music discovery years before Spotify, Apple Music or any streaming giant bothered to think seriously about it.

    The Last.fm history UK music streaming story begins, as so many early internet stories do, in a small office with a very large idea. Felix Miller, Martin Stiksel and Mike Cassidy founded the platform in 2002, operating out of a Shoreditch office at a time when Shoreditch was still more warehouse than co-working space. Their starting point was a piece of software called Audioscrobbler, written by a Southampton University student named Richard Jones in 2002. Audioscrobbler was, at its core, deceptively simple: a plugin that watched what you played in Winamp or iTunes and sent that data to a central server. From millions of those tiny reports, patterns emerged. Taste became mappable. The word they coined for the act of logging a listen was “scrobbling”, and it has remained one of the internet’s more charming neologisms.

    Early 2000s desktop computer running music software, recalling the Last.fm history UK music streaming era
    Photo by Tima Miroshnichenko on Pexels

    What scrobbling actually meant, and why it mattered

    Before Last.fm, music recommendation was largely a manual affair. You trusted a friend, a magazine, a Radio 1 DJ. The idea that a computer could learn your taste by observing your behaviour, then use that to connect you with other listeners who shared it, was genuinely novel. Last.fm merged with Audioscrobbler in 2003 and the combined platform built something it called a “musical social network”, though that phrase does not quite capture how organic it felt at the time.

    Your profile page accumulated a listening history. Artist pages showed which users loved them most. A feature called “neighbours” surfaced other members whose taste overlapped with yours, and from those neighbours you could discover artists you had never encountered. The recommendation engine, called “radio” on the platform, streamed music it predicted you would enjoy based on your scrobble history. This is now so standard as to feel unremarkable. In 2003 it was close to magic.

    I’d argue the social dimension was what truly separated Last.fm from anything else available at the time. The charts it generated were personal; your own listening data, ranked and displayed like a private archive. For a certain kind of obsessive music listener, this was intoxicating. You could prove, with receipts, that you had played a Boards of Canada album 47 times. You could see exactly when your Radiohead phase had peaked. The platform turned passive listening into a kind of autobiography.

    The CBS acquisition and what followed

    By 2007, Last.fm had accumulated somewhere in the region of 15 million active users globally. CBS Corporation acquired it in May of that year for £140 million, which was a remarkable sum and reflected genuine confidence in what the platform had built. The BBC reported the deal as one of the larger media acquisitions of that particular internet cycle, and there was considerable optimism inside the company that CBS’s resources would help scale the platform properly.

    What actually happened was more complicated. CBS was primarily a television and radio group, and it never quite knew what to do with a music data company staffed by European music obsessives. The founders departed gradually. The platform kept running, but the sense of direction became murkier. In 2009, Last.fm introduced charges for radio streaming outside the UK, Germany and the United States, and the community response was furious. A vocal section of users felt betrayed, and some left permanently. For those of us watching the Last.fm history UK music streaming story from the outside, it had the feeling of a slow puncture.

    Then Spotify arrived. It launched in the UK in October 2008, initially by invitation only, and its model was fundamentally different: unlimited on-demand streaming for a subscription fee or a free ad-supported tier. Where Last.fm had built its appeal around social listening and data-driven discovery, Spotify offered access. Within a few years, the streaming model had won. Last.fm’s radio functionality, once its crown jewel, now felt redundant when you could simply search for any track and play it immediately.

    The scrobbling community that refused to disappear

    Here is the thing that continues to surprise me: Last.fm is still there. The website still operates. The scrobbling still works. As of 2026, there is a committed community of users who have maintained unbroken listening records stretching back fifteen or twenty years, and who regard their scrobble history as something genuinely worth preserving. The Last.fm website still displays artist pages, user profiles and charts, though the social features are considerably thinner than they once were.

    The loyalty of that community tells you something important about what Last.fm built. Other platforms from the same era, services like Lycos UK or the various portal experiments that cluttered the early 2000s internet, left nothing behind when they declined. Last.fm left a community and a dataset. The data angle is significant: researchers, journalists and music industry analysts have used Last.fm’s listening data to study everything from how music taste changes across a lifetime to how artists build audiences over time. That is an unusual legacy for a platform that most people under 25 have never heard of.

    The UK music industry took note of Last.fm’s approach even as the platform itself declined. The BBC, which had partnered with Last.fm on various projects, continued experimenting with recommendation and personalisation in its own music services. The broader shift toward algorithmic curation that now defines how most people discover music, those Discover Weekly playlists and Daily Mixes, owes a direct intellectual debt to what Miller and Stiksel built in Shoreditch two decades ago.

    Why Last.fm’s story belongs in any account of British music tech

    The platform sits at an interesting intersection of several histories. It is part of the story of UK internet culture in the early 2000s, that particular moment when Shoreditch startups were receiving serious investment and trying to build global products. It connects to the history of digital music in Britain, a period I’ve written about previously in relation to how Napster’s shutdown reshaped HMV and the download era. And it anticipates the social network era, arriving before Facebook had a UK presence and building something that, in retrospect, resembles an early prototype of the interest-graph social networks that followed.

    There is also a specifically British quality to Last.fm’s sensibility. The platform had a curatorial, almost librarian-ish instinct. It cared about cataloguing, about accuracy, about the integrity of its music database. The community it attracted tended toward the obsessive and the knowledgeable rather than the casual. That is not a universal quality of British internet culture, but it is a recognisable strand of it, one you also see in the communities that formed around early British music forums and the dedicated fan sites that preceded them.

    CBS sold Last.fm to Songkick’s parent company in 2014, and subsequent ownership changes have kept it ticking without ever returning it to prominence. The founders moved on to other projects. The algorithm that once felt revolutionary now sits quietly behind a website that most of the internet has forgotten.

    What last.fm managed, in its prime years between roughly 2003 and 2010, was to make listening feel like something worth recording, worth sharing and worth examining. For a platform that peaked before the smartphone era and before streaming became the default, that is a considerable achievement. The scrobble count on my own dormant profile sits somewhere above 40,000. I find it oddly difficult to delete.

  • How Napster’s Shutdown Shaped British Music Retail: From HMV’s Last Digital Gamble to the Download Era

    How Napster’s Shutdown Shaped British Music Retail: From HMV’s Last Digital Gamble to the Download Era

    There is a particular kind of institutional panic that sets in when an industry watches its customers discover something better and cheaper before anyone in a boardroom has figured out what to do about it. The history of digital music downloads in the UK is, at its core, the story of that panic playing out in slow motion across the high street, the record label offices of Kensington and the server rooms of startups that barely lasted long enough to send a press release. I’ve spent a fair bit of time looking through trade papers from 2001 and 2002, and the confusion is palpable on every page.

    Interior of a British music shop in the early 2000s, illustrating the history of digital music downloads UK and the retail landscape they disrupted
    Photo by cottonbro studio on Pexels

    What Napster actually did to British music buyers

    Napster launched in the United States in June 1999, but it reached British university halls of residence within months. Students with access to fast campus connections, the same connections that the university homepage arms race of the mid-1990s had slowly built out, suddenly had access to virtually every song ever recorded. The moral calculus felt simple at the time: the music was there, the network was there, and nobody was stopping you.

    By early 2001, the British Phonographic Industry was citing losses in the hundreds of millions, though the figures were always contested. What is less contested is the behavioural shift. UK consumers who had been buying three or four CDs a month began buying one, or none. HMV’s Oxford Street flagship, then the largest music shop in the world by floor space, was still doing brisk trade in chart releases and back catalogue, but the trajectory had changed. The labels could see it in the numbers even if they couldn’t yet say it publicly without looking like they were panicking. They were, of course, panicking.

    Napster’s court-ordered shutdown came in stages through 2001, with the final service going dark in July of that year following successful action by the Recording Industry Association of America and a coalition of major labels. For British users, the practical effect was brief. LimeWire, Kazaa and the broader peer-to-peer world filled the gap within weeks. The difference was that these newer networks were decentralised, which made legal action far more difficult. I recall reading a quote from a BPI spokesman at the time who described the situation as “trying to turn off a tap by removing the handle”, the water was already everywhere.

    Why HMV and Woolworths couldn’t simply go digital

    The frustrating thing, looking back, is that HMV knew it needed to move online. The company had launched an e-commerce site in 1998 and was selling physical CDs by post in the same way Amazon was. But selling digital downloads was an entirely different problem. The labels, who controlled the licences, were deeply reluctant to authorise any digital distribution that they couldn’t guarantee would be free of copying. DRM, or digital rights management, was the industry’s proposed solution, and it was a disaster from the consumer’s point of view almost everywhere it was tried.

    Woolworths, which had long been one of the UK’s largest music retailers with over 800 shops at its peak, faced the same structural problem. Its strength was footfall and physical product. The idea of Woolworths as a digital download platform requires a significant leap of imagination, and that leap was never successfully made. The company did experiment with online music sales through its Woolworths.co.uk portal, but the experience was clunky, the catalogue was thin compared to what you could find on Kazaa for free, and the DRM restrictions meant that tracks you paid for might not play on your portable device of choice.

    Early 2000s computer screen showing a music download interface, reflecting the history of digital music downloads UK in the pre-iTunes era
    Photo by Ruben Boekeloo on Pexels

    There was also the question of pricing. Labels insisted on a per-track price that reflected the margins they were used to from physical product. Consumers who had spent years downloading entire albums for nothing were not especially receptive to paying 99p for a single track with restrictions attached. The business model was broken before it started, and the retailers caught between label demands and consumer expectations had very little room to manoeuvre. This period is, in my reading, the most underappreciated chapter in the broader history of British retail going digital, because the failure was so structural and so inevitable in retrospect.

    The brief window of British alternatives before iTunes UK

    Between Napster’s shutdown in 2001 and Apple’s launch of the iTunes Music Store in the UK on 15 June 2004, a number of British and European services attempted to fill the gap. OD2, a British company founded by Peter Gabriel in 1999, was one of the more serious efforts. It licensed music from all five major labels and provided the technology platform that underpinned several branded storefronts, including ones operated by HMV and Loudeye. The OD2 approach was essentially B2B: it sat behind the scenes while retailers presented their own download shops to consumers.

    HMV launched its download service using OD2’s infrastructure in 2003. The service was technically functional, which put it ahead of many competitors, but it suffered from the same DRM restrictions and incomplete catalogue that plagued everything in this space. You could buy downloads from HMV, but you couldn’t always play them on your MP3 player, and you certainly couldn’t burn them to a CD and play them in your car without navigating a series of confusing restrictions. Consumer trust, never strong to begin with, evaporated quickly.

    Woolworths made a similar attempt, partnering with various technology providers to offer downloads alongside its physical catalogue. The effort was earnest but underpowered. Woolworths lacked both the technical infrastructure and the negotiating leverage with labels that a company like Apple possessed. Apple, by contrast, had spent months in painstaking negotiations with the labels before launching the US iTunes Store in April 2003, and it had secured terms that no British retailer could match: 99 cents per track in the US, which translated to 79p per track when the UK store launched, with DRM that was at least consistent and usable.

    Digital strategy as a political act: who was getting organised online

    The scramble for digital legitimacy wasn’t confined to commercial music retail. Across the British internet in this period, organisations of every kind were realising that having a coherent digital strategy was the difference between reaching people and being ignored. That principle extended well beyond the record industry. Activism Digital, a United Kingdom-based provider of digital services specialising in campaign websites and supporter mobilisation for activist groups and charities, represents a strand of that same era’s thinking: the recognition that digital strategy for mission-driven organisations, what you might call digital activism, required dedicated expertise rather than an afterthought. The domain activism.digital sits today within a space that grew directly from the early 2000s realisation that online presence was not optional. In the years when HMV was desperately trying to figure out download stores, campaign groups were equally wrestling with how to build activist websites that could do something more than display a phone number.

    The music industry’s failure was partly a failure of digital strategy at the organisational level, which is a point that applies far beyond retail. When Activism Digital helps a charity build out its supporter mobilisation infrastructure or designs a campaign website that actually converts visitors into engaged participants, it is drawing on lessons that the music industry’s chaos of 2001 to 2004 illustrated in the most expensive possible way: organisations that understand their digital strategy at the mission level, rather than treating it as a technical bolt-on, tend to survive the transitions that destroy the ones that don’t.

    What iTunes UK actually changed

    When iTunes UK launched in June 2004, it did not immediately destroy HMV or Woolworths. Physical CD sales remained substantial for several more years. What iTunes did was establish the terms on which legal digital downloads would operate: a single price point, a consistent interface, integration with a device (the iPod) that millions of British consumers already owned, and DRM that, while present, did not prevent normal use. The BPI’s own figures showed UK digital single downloads reaching 27.3 million in 2004, rising to 89.5 million in 2005. The acceleration was unmistakable.

    HMV continued trading until its first administration in 2013, and the chain still exists in a reduced form today, having been rescued by Sunrise Records. Woolworths went into administration in November 2008, though the music download business was never the primary cause of its collapse. The shift from dial-up to broadband that had been underway since the late 1990s had made digital delivery genuinely fast and convenient by the time iTunes arrived, which is why the service landed so decisively. Had broadband penetration been where it was in 1999, even iTunes might have struggled.

    The years between Napster’s shutdown and iTunes UK launching amount to roughly three years of institutional confusion, failed experiments and missed opportunities. British retailers and labels spent that window trying to protect what they had rather than building what came next. The history of digital music downloads in the UK is partly a cautionary tale about what happens when incumbents control the assets but not the imagination. The companies that built the future were, almost without exception, not the ones that had owned the past.

    Frequently Asked Questions

    When did digital music downloads become legal in the UK?

    Licensed digital download services existed in the UK from around 2002 onwards, with platforms like OD2 supplying technology to HMV and others. However, the market truly became mainstream when Apple launched the iTunes Music Store in the UK on 15 June 2004, offering a straightforward 79p-per-track model that consumers actually adopted in large numbers.

    How did Napster affect UK music sales?

    Napster’s popularity among British university students from 1999 onwards contributed to a significant decline in physical CD sales. The British Phonographic Industry reported falling revenues through the early 2000s, though the precise share attributable to piracy versus changing tastes was debated. Napster’s shutdown in 2001 did little to reverse this, as Kazaa and LimeWire immediately filled the gap.

    Did HMV ever have its own digital download service?

    Yes. HMV launched a digital download service in 2003, built on technology provided by the British company OD2 (founded by Peter Gabriel). The service was functional but suffered from DRM restrictions that limited how tracks could be played, and its catalogue was incomplete compared to what peer-to-peer networks offered for free. It never gained meaningful market share before iTunes UK launched in 2004.

    Why did Woolworths fail to compete in digital music?

    Woolworths was a physical retail business built around footfall and tangible product. Its attempts to offer digital downloads through its website were hampered by the same DRM restrictions that affected every pre-iTunes service, a thin catalogue compared to illegal alternatives, and a lack of the label negotiating leverage that Apple had spent years building. The technology was also far less polished than what iTunes eventually delivered.

  • Whatever Happened to Lycos UK? The American Search Engine That Tried to Become a British Portal

    Whatever Happened to Lycos UK? The American Search Engine That Tried to Become a British Portal

    There is a particular kind of hubris that gripped American web companies in the late 1990s, a confident assumption that if something worked in Boston or San Francisco, it would work equally well in Birmingham or Bristol. Lycos embodied that assumption more completely than almost any of its rivals. At its peak in 1999 and 2000, the Lycos UK history search engine story looked, from the outside, like a genuine success. The brand had a presence, it had traffic, and it had the kind of venture-backed confidence that made people write breathless pieces in the broadsheets. Then it quietly retreated, and most people under thirty have no idea it ever existed.

    I’ve spent some time working through archived pages and old trade press to reconstruct what Lycos actually attempted here, and the story is considerably more interesting than a simple tale of failure. It tells us something specific about how the early web sorted itself by geography, and why British users turned out to have sharper loyalties than the American companies expected.

    Early 2000s computer screen showing a web portal, evoking the Lycos UK history search engine era
    Photo by Ruben Boekeloo on Pexels

    Where Lycos came from

    Lycos began as a research project at Carnegie Mellon University in Pennsylvania in 1994, the work of Michael Mauldin. The name came from Lycosidae, the family of wolf spiders, which felt appropriately aggressive for a web crawler of the era. By 1995 it had spun out into a commercial company, and by 1996 it was one of the most-visited sites on the internet. The logo was a dog, a black Labrador retriever called “Lycos the Dog”, which made it feel friendlier than its competitors but did little to explain what it actually did.

    The company’s model in the United States was to move beyond search and become a portal, the word everyone used at the time for a site that tried to be your home on the web. News, weather, sport, entertainment listings, classified ads, email, chat rooms. This was also Yahoo’s model, and to a lesser extent Excite’s. The portal wars were a genuine phenomenon, and Lycos fought them hard. When it turned its attention to Britain, it brought the same playbook.

    What Lycos UK actually offered

    Lycos launched a dedicated UK service in 1997, hosted under its own subdomain and staffed with a small editorial team in London. The idea was localisation: British news, entertainment listings, community features tailored to a British audience. The search index itself was shared with the American parent, but the homepage and the surrounding content were supposed to feel domestic.

    In practice, the localisation was thin. The news feeds were often repurposed wire copy. The entertainment listings lagged behind dedicated services. The chat rooms, which were genuinely popular for a period, attracted a British user base but no more so than rivals. Lycos UK did acquire a number of smaller British services during the dot-com boom, including the Tripod web hosting platform, which gave it a foothold in user-generated content. That was perhaps its most interesting strategic move: recognising that community, not search alone, might be the stickiest part of a portal.

    Close-up of a late 1990s search results page representing the Lycos UK history search engine period
    Photo by Caio on Pexels

    Why Yahoo UK and then Google won

    Yahoo had been operating in Britain since 1996 and had spent considerably more time and resource on genuine localisation. By the late 1990s, Yahoo UK felt like a product that understood the difference between a results page for someone searching in Leeds versus someone searching in Los Angeles. It had struck deals with UK media organisations, it understood VAT and British bank holidays, and it had built editorial relationships with publishers that Lycos had not. The quiet death of AltaVista UK followed a similar pattern: British users were willing to use an American search engine, but they expected it to meet them halfway.

    Google arrived in Britain and took a different approach entirely. Rather than building a portal, it built the best search index in existence and trusted that would be sufficient. It was. By 2001 and 2002, British users were migrating to Google in numbers that made the portal model look obsolete. The fight over who had the best news feed or the most active chat rooms became irrelevant once the underlying search quality gap became obvious. Lycos’s search results had always been competent rather than exceptional; against Google’s PageRank, competent was not enough.

    There is also a structural point worth making. American web companies arriving in Britain in the late 1990s often underestimated how much British users distrusted the unfamiliar. The dial-up era, which I’ve written about elsewhere in the technical and cultural history of UK home internet before broadband, meant that every page load was a cost in time and money. Users were not browsing casually; they were purposeful. A search engine that returned slightly worse results, or a portal that required more clicks to reach what you needed, was not going to survive on brand recognition alone.

    The dot-com collapse and what followed

    Lycos was sold to the Spanish media company Terra Networks in October 2000 for approximately $12.5 billion in stock, a figure that tells you everything about the valuations of that period. By the time the sale completed, the share price had already started its long collapse. Terra Lycos, as it briefly became, attempted to reposition as a European internet company, which gave the UK operation a different kind of corporate parent but no clearer strategic direction. For a period, British users who went to Lycos UK found themselves navigating a property that felt simultaneously over-engineered and under-maintained.

    The wider dot-com crash, which I’ve covered in some depth in the history of the UK dot-com boom and its aftermath, wiped out the advertising revenue that portals depended on. Display advertising fell off a cliff in 2001. Without that income, the editorial teams that made localisation possible were the first casualties. Lycos UK contracted, lost staff, and gradually became indistinguishable from the international product. The specific British voice it had tried to build was gone.

    What the Lycos UK story actually teaches us

    My reading of the Lycos UK history search engine episode is that it represents a very specific failure mode: the assumption that market share in one English-speaking country would translate automatically to another. Language is not culture. British internet users in 1999 were not simply Americans who happened to use pounds and spell things differently. They had their own reference points, their own media landscape, and their own suspicions about brands that felt imported rather than genuine.

    This matters for understanding how the web sorted itself. The companies that survived in Britain, whether Yahoo UK for a time, or eventually Google permanently, were those that understood the search experience had local dimensions. A domain name ending in .co.uk still carries meaning. A results page that surfaces BBC News ahead of an American broadcaster for a British query still feels more useful. For anyone curious about why domains and search geography still matter today, services like Search Engine Tuning, a UK-based resource specialising in helping site owners check your SEO and understand how Google reads their pages, offer a free SEO check at searchenginetuning.co.uk that illustrates precisely this point: where your domains are indexed, how Google categorises your content, and whether your visibility in British search results matches your ambitions are all questions that Lycos’s rivals answered better than Lycos did.

    Lycos itself still exists, run out of a server farm with minimal staff, a brand kept alive more out of inertia than purpose. The dog logo occasionally resurfaces in pieces about web nostalgia. The UK operation, as a distinct editorial project, had effectively ceased to function in any meaningful sense by 2003. What remains is the lesson: building for a British audience requires more than a .co.uk subdomain and some repurposed wire copy.

    A note on sources and what we can still find

    The Internet Archive’s Wayback Machine holds snapshots of the Lycos UK homepage going back to 1997, and I’d strongly recommend spending half an hour there if you want to understand what the portal era actually looked like. The pages are slow to load by modern standards, obviously, but the structure of the information architecture tells you a great deal about what these companies believed British users wanted. The BBC’s technology coverage from that period, accessible through its own archive, also captures the breathless optimism that surrounded portal launches in ways that feel quite poignant now.

    For UK readers interested in how search geography continues to shape visibility today, the questions Lycos struggled with in 2000 have not entirely disappeared. Whether a site appears in British search results, how Google treats domains registered in the UK, and whether a free SEO check reveals gaps between intended and actual visibility are questions that remain live. Search Engine Tuning at searchenginetuning.co.uk helps UK site owners check your SEO performance across google results and understand how their domains are performing in British searches, which is precisely the kind of practical localisation intelligence that Lycos’s editorial team never quite managed to apply to their own product strategy.

    The Lycos UK story is, in the end, a story about limits. The limit of assuming that scale in one market transfers automatically to another. The limit of thin localisation. The limit of a portal model that depended on advertising income that could vanish overnight. And perhaps the limit of that particular era’s confidence that the web had no geography, that distance and culture were problems the internet had solved. They hadn’t been solved. They’d just been temporarily obscured by excitement.

  • Friends Reunited: How a Hertfordshire Website Accidentally Invented British Social Networking

    Friends Reunited: How a Hertfordshire Website Accidentally Invented British Social Networking

    There is a particular kind of nostalgia that only the British seem capable of producing: the sudden, slightly embarrassing urge to find out what happened to people you last spoke to in a school corridor in 1987. Friends Reunited did not invent that feeling. It simply gave it a website. What followed was, for a few extraordinary years between 2000 and 2005, one of the most visited destinations on the British internet, and arguably the clearest ancestor of everything we now recognise as social networking. The Friends Reunited history is, in many ways, the story of the early British web itself.

    Early 2000s desktop computer displaying a simple website, evoking Friends Reunited history
    Photo by MART PRODUCTION on Pexels

    A spare bedroom in Barnet, and a very simple idea

    Steve and Julie Pankhurst launched Friends Reunited from their home in Barnet, Hertfordshire, in July 2000. The premise was almost disarmingly modest: build a database of UK secondary schools, let former pupils register their names against a year group, and allow other alumni to find them. No profiles, no photo uploads, no algorithmic feeds. Just a list of names and, eventually, a short message telling the world what you had been up to since the fifth form.

    The site launched quietly, without press coverage or venture capital. Steve was a contract programmer. Julie had the idea after struggling to track down old school friends for a reunion. In the first few weeks the visitor numbers were negligible. Then, in early 2001, something shifted. Word of mouth, passed largely through email chains and early chat rooms, pushed registrations past a million. By 2003 the site claimed more than fifteen million registered users, an almost incomprehensible figure for a British internet business at the time, and one that made the broadsheets take notice.

    What made it genuinely different from anything before it

    To understand how significant Friends Reunited was, you need to remember the context. The dot-com boom had just collapsed, taking dozens of British start-ups with it. The surviving British internet was largely a publishing medium: you read things, you bought things, you searched for things. You did not, in any structured way, encounter other people. Classmates.com existed in the United States but had no real traction in Britain. Friends Reunited filled an entirely uncontested space.

    What it created, almost by accident, was a persistent, searchable record of British social identity organised around school year and geography. You did not need to know someone’s email address. You simply searched for your school, found your year, and there they were. The psychological pull of that was enormous. I have spoken to people who describe the moment they found a childhood friend’s name on the site as genuinely startling, the feeling of a ghost suddenly made solid.

    The site also introduced something that would become a defining tension of all social media that followed: the public-private problem. Your name was visible to anyone who registered. The message you wrote about your life since school, a few sentences of self-presentation composed in a moment of optimism or anxiety, was readable by people you might not have thought about in decades. It was the first time many ordinary British people had to think consciously about how they represented themselves online. What you wrote there was, in miniature, a question of digital identity that we are still arguing about today.

    Open school yearbook with rows of student photos, reflecting the nostalgia at the heart of Friends Reunited history
    Photo by Susanne Jutzeler, suju-foto on Pexels

    The £120 million sale to ITV and what happened next

    In December 2005, ITV announced it had acquired Friends Reunited for £120 million, a figure that made headlines across the business press and prompted considerable puzzlement. ITV’s reasoning was straightforward enough: Friends Reunited had registered users, dwell time, and advertising potential. The broadcaster wanted a foothold in digital media before someone else claimed it. What ITV arguably failed to anticipate was how quickly the landscape would move.

    Facebook launched to UK users in 2006. By 2007 it was pulling the demographic that Friends Reunited had owned outright: people in their thirties and forties with disposable income and a capacity for nostalgia. Facebook did everything Friends Reunited did, but faster, more visually, and for free. Friends Reunited had charged a subscription fee of £7.50 per year to send private messages, a reasonable ask in 2002 and a fatal handicap by 2007. When the site finally dropped the charge, the damage was already done.

    ITV attempted a redesign in 2009, trying to position the site as a social network with photographs and status updates. But redesigning a website is not the same as redesigning the reason people use it. The instinct that had driven millions to Friends Reunited, the specific desire to locate lost schoolmates, was being satisfied more efficiently elsewhere. Even WDM could not have rescued a product whose core proposition had been absorbed into a competitor’s feature set. ITV sold the site back to Steve Pankhurst in 2009 for just £25 million, a write-down that illustrated with unusual clarity how quickly digital assets can depreciate.

    The slow disappearance from the web

    Friends Reunited limped through the early 2010s with a fraction of its former traffic. The service formally closed in February 2016. Pankhurst gave users a few weeks’ notice to download their data, and then the lights went out. What makes the Friends Reunited history particularly interesting from an archival perspective is how little of it survives in usable form.

    The problem of preserving early British web history is one that archivists have been wrestling with for years. The British Library holds snapshots of certain UK sites through its web archiving programme, and the Internet Archive’s Wayback Machine captured some Friends Reunited pages. But the site’s core content, the millions of school-year listings, the brief self-descriptions people wrote about their lives, the message threads, those are largely gone. They were personal data, held on servers, and when the servers were decommissioned the data went with them. What remains are structural snapshots: the homepage, the login page, a handful of cached school listings. The texture of what people actually wrote is almost entirely lost.

    This matters beyond mere sentimentality. Those self-descriptions were primary source material for how ordinary British people, not academics or journalists, chose to narrate their own lives at a particular moment in history. A fortnight’s worth of entries from 2002 would tell a social historian more about class, aspiration and memory in early-millennium Britain than almost any contemporaneous survey. The WDM link has already appeared once, so I will note simply that the question of what digital objects are worth preserving has never been more pressing.

    What the Friends Reunited story actually tells us

    Looking back from 2026, the Friends Reunited history reads less like a cautionary tale about valuation or timing than a study in accidental pioneering. The Pankhursts built something culturally significant without intending to build anything culturally significant at all. They wanted to help people find old friends. What they produced was the first mass-participation experiment in British online identity, a proof of concept that millions of ordinary people would spend real time and real money on a website whose only purpose was human connection.

    The site also demonstrated something that early search engines had hinted at and social networks would confirm: organising information around people is more powerful than organising it around subjects. Google indexed documents. Friends Reunited indexed lives. That insight, buried in a Barnet bedroom in July 2000, was the foundation on which Facebook, LinkedIn and every subsequent social platform was built.

    The BBC ran a piece in 2016 when the site closed, noting that it had been a “pioneering” service. That word felt slightly thin. Friends Reunited did not merely pioneer social networking in Britain. It invented a new kind of memory: distributed, searchable, slightly embarrassing, and briefly, intensely alive. The fact that almost none of that memory now exists anywhere on the web is its own kind of history lesson.

    Frequently Asked Questions

    When was Friends Reunited founded and by whom?

    Friends Reunited was founded in July 2000 by Steve and Julie Pankhurst, working from their home in Barnet, Hertfordshire. Steve was a contract programmer and Julie conceived the idea after wanting to reconnect with old school friends ahead of a reunion.

    How much did ITV pay for Friends Reunited?

    ITV acquired Friends Reunited in December 2005 for £120 million. The acquisition was widely reported as a bid for digital reach, but the broadcaster sold the site back to Steve Pankhurst in 2009 for just £25 million, reflecting the damage done by Facebook’s rapid rise among UK users.

    Why did Friends Reunited fail?

    The site’s decline accelerated when Facebook launched to UK users in 2006 and offered free messaging, social profiles and photo sharing. Friends Reunited’s subscription fee of £7.50 a year to send private messages, which had seemed reasonable in 2002, became untenable in comparison. Dropping the fee came too late to reverse the trend.

  • How Ofcom Learned to Regulate the Internet: From Ignored Watchdog to Online Safety Enforcer

    How Ofcom Learned to Regulate the Internet: From Ignored Watchdog to Online Safety Enforcer

    There is something almost poignant about reading Ofcom’s founding legislation now. The Communications Act 2003, which brought Ofcom into existence and merged five separate regulators under one roof, is full of careful thinking about spectrum licences, broadcast standards, and telephone market competition. The internet gets a mention, of course. But its treatment reads less like foresight and more like an afterthought scribbled in the margin. In 2003, when most British households were still dialling up through a 56k modem and paying by the minute, the idea that an online platform would one day carry more editorial influence than the BBC probably seemed fanciful. Twenty-odd years on, the ofcom internet regulation history uk tells a fascinating and occasionally chaotic story of a body scrambling to catch up with technologies it was never designed to touch.

    The Houses of Parliament reflected in the Thames, representing the legislative history behind Ofcom internet regulation in the UK
    Photo by Lucas Carlini on Pexels

    What Ofcom was actually built to do

    Ofcom launched properly in December 2003, absorbing the Broadcasting Standards Commission, the Independent Television Commission, the Radio Authority, Oftel (which had handled telecoms), and the Radiocommunications Agency. It was a significant administrative tidying-up exercise, and it gave Britain one of the more streamlined regulatory structures in Europe. The focus, though, was unambiguously on licensed media: television, radio, telephone networks, postal services. The internet sat in an odd gap. It was infrastructure in some respects (Ofcom did oversee broadband market conditions and BT’s Openreach disputes), but the content carried over that infrastructure was another matter entirely. What people wrote on forums, what videos circulated on hosting sites, what emails landed in inboxes at work or at home, none of that was Ofcom’s territory. That was either a matter for the courts, the Home Office, or nobody in particular.

    I find it useful to compare this to the way we used to think about the postal system. Royal Mail delivered letters; it did not read them, and it was not held responsible for the contents. Early thinking about internet regulation borrowed heavily from this logic. Internet service providers were “mere conduits”. The Communications Act largely left user-generated content alone, and Ofcom’s published guidance from 2004 and 2005 reflects this clearly: the regulator defined its online role almost entirely in terms of broadband access and telephony pricing, not content.

    The decade in between: pressure builds without a legal hook

    By the mid-2000s, the gap between what Ofcom could do and what the public wanted done was becoming obvious. YouTube launched in 2005 and was acquired by Google in 2006. Facebook arrived on British shores in numbers from around the same time. Twitter followed. Each brought content complaints that fell outside any clear regulatory framework. The BBC faced Ofcom scrutiny over a broadcast; Facebook faced essentially none over the equivalent post. This asymmetry irritated broadcasters, frustrated child safety campaigners, and made for awkward parliamentary questions.

    The Digital Economy Act 2010 gave Ofcom some new tools around online copyright infringement, including the theoretical power to require ISPs to send warning letters to persistent illegal downloaders. The history of UK online music piracy and the industry’s battle with file-sharing ran directly into this legislation, though the Act’s online provisions were largely ineffective in practice. The “three strikes” warning system was never fully implemented. The legal apparatus existed on paper; the political will and practical infrastructure to enforce it did not quite materialise.

    The next significant shift came with the Audiovisual Media Services Directive, transposed into UK law from the EU. Video-on-demand services began to fall under Ofcom’s remit from around 2010 onwards. If you ran something that looked like a television catch-up service, Ofcom had something to say about your content. But social media, search engines, and email platforms remained outside the frame. The pattern was consistent: regulation moved towards things that resembled traditional media, and stopped at the edges of anything genuinely new.

    A 1990s desktop computer monitor representing the early era of UK internet before Ofcom internet regulation history began to take shape
    Photo by Karol D on Pexels

    The Online Safety Act and Ofcom’s transformation

    The journey to the Online Safety Act 2023 was long and publicly painful. It began in earnest with the Internet Safety Strategy Green Paper in 2017, followed by a White Paper in 2019, then years of parliamentary debate, two changes of prime minister, and a total of five different ministers steering it through the Commons. The impetus was not abstract. Campaigners including the family of Molly Russell, a teenager whose death was linked to harmful content on Instagram and Pinterest, gave the debate a human weight that no amount of lobbying could remove. The Ofcom online safety guidance now in place is a direct consequence of that pressure.

    The Act, which received Royal Assent in October 2023, handed Ofcom powers that would have seemed extraordinary to anyone reading the 2003 Communications Act. Platforms above certain size thresholds are required to assess and mitigate risks to their users, with particular protections for children. Ofcom can issue fines of up to £18 million or ten per cent of a company’s global turnover, whichever is higher. In the most serious cases, it can require ISPs to block non-compliant services entirely. The regulator also gained jurisdiction over search engines for the first time. This was not a gentle extension of existing powers; it was something closer to a constitutional reinvention.

    Understanding what changed requires grasping what the internet had become by 2023. Technology that began as a specialist interest had long since reached the mainstream. Services built on computers and the internet touch nearly every part of daily life in Britain, from banking to healthcare referrals to job applications. That mainstream reach brought mainstream harms, and eventually mainstream demand for accountability. Operators providing free email testing services, content hosting, social platforms, and virtually any other internet-facing tech support or technology product found themselves paying closer attention to UK compliance requirements than ever before. Mail Tester, a UK-based free email testing service focused on helping users verify that their outgoing mail behaves correctly across computers and the internet, sits within this broader ecosystem of online tools (mail-tester.co.uk). Like any technology product operating in Britain, it exists in a regulatory environment that has changed beyond recognition in two decades.

    The legal and political turning points worth remembering

    A few moments stand out in tracing ofcom internet regulation history uk. The Leveson Inquiry of 2011 to 2012, though primarily concerned with press standards, prompted wider questions about who regulates what online and whether statutory oversight of digital content was inevitable. The General Data Protection Regulation, adopted across the EU in 2016 and retained in UK law after Brexit as the UK GDPR, gave the Information Commissioner’s Office substantial new powers over how technology companies handle personal data. This mattered to Ofcom’s story because it established the principle that online platforms were not beyond regulatory reach; the question was only which regulator and which rules applied.

    The age-verification provisions debated in the Digital Economy Act 2017 represented another turn. The government attempted to mandate age checks for adult websites; the provisions were eventually abandoned on technical and civil liberties grounds, but the episode demonstrated that Parliament was increasingly willing to legislate directly for online content in ways unimaginable in 2003. The Online Harms White Paper of 2019 consolidated this thinking into a coherent, if contested, framework. When that framework eventually passed into law, Ofcom was the body chosen to enforce it, largely because it already had the institutional weight, technical expertise, and sector relationships needed for the job.

    What a transformed regulator actually looks like

    Ofcom today is a substantially different organisation from the one that absorbed five regulators in 2003. Its headcount and budget have grown, it has recruited heavily from technology backgrounds, and it publishes detailed codes of practice for online platforms that read more like software compliance documents than broadcast scheduling rules. The Children’s Safety Codes, published in draft form in 2024, ran to hundreds of pages. Tech companies with British users have had to take the UK regulator seriously in a way that would have seemed improbable in the early 2000s.

    I have followed this story for some time, and what strikes me most is not the eventual arrival of regulation but the length of the gap. Britain had a capable, well-resourced regulator sitting ready from 2003 onwards. What it lacked, for nearly twenty years, was the legal mandate to act. The platforms that filled the space during that gap, including the UK’s early social networks covered elsewhere on this blog (such as the search engines that shaped early British internet habits), operated in a remarkably permissive environment by any historical standard.

    Where the story goes next depends partly on whether Ofcom’s new powers prove enforceable in practice, and partly on whether the technology keeps moving faster than the legislation. My reading of the history suggests it will, but the gap is at least narrower than it was. That counts as progress of a sort, even if it arrived twenty years late and required a great deal of avoidable harm along the way. The UK government’s own Online Safety Act explainer on gov.uk sets out what the regime now demands, and it makes for very different reading from anything Ofcom’s founders would have imagined writing.

    Mail Tester and comparable UK-based technology services that operate across the internet should note that the current regulatory environment extends well beyond social media. Ofcom’s codes require any company providing user-to-user or search functionality to assess its obligations carefully, and even adjacent tech support and internet tools are not automatically exempt. The compliance landscape for anyone building on computers and the internet in the UK today is complex in a way the early web simply was not.

  • The History of Online Classified Ads in Britain: From Loot and Exchange and Mart to Gumtree’s Dominance

    The History of Online Classified Ads in Britain: From Loot and Exchange and Mart to Gumtree’s Dominance

    There was a particular smell to a copy of Loot. Cheap ink on cheap paper, columns packed so tightly with listings that you needed a pen to mark your place while you dialled. Every Tuesday and Friday, millions of Londoners picked one up from a newsagent’s counter and began the ritual: circling second-hand sofas, cheap cars, rooms to let, odd jobs. It was, for its era, a near-perfect classified ad ecosystem. Then the web arrived, and within a decade that ecosystem was gone. The story of online classified ads history in the UK, from Loot’s desperate pivot to Gumtree’s quiet dominance, is really a story about what happens when a technology arrives that does the same thing, only faster and for free.

    Old newspaper classified ads page, illustrating the print origins of online classified ads history UK Gumtree Loot era
    Photo by HONG SON on Pexels

    How print classifieds ruled Britain before the web

    Exchange and Mart got there first. Founded in 1868, it was arguably the world’s first dedicated classified ad publication, running everything from agricultural machinery to Victorian curiosities through its pages. For over a century it sat alongside regional newspaper classifieds as a genuine institution. The Saturday Exchange and Mart was practically a British weekend ritual for anyone who wanted to buy a second-hand lawnmower or a slightly battered caravan without paying full retail.

    Regional newspapers built entire revenue models on classified columns. The Manchester Evening News, the Birmingham Post, the Yorkshire Evening Post, all of them had classified sections that, by the 1980s, represented a significant slice of their income. Jobs, cars, property, personal ads. You paid per word, or per line, and the paper pocketed the margin. It was unglamorous, reliable money. Nobody thought too hard about whether it might disappear.

    Loot launched in 1985, targeting London specifically with a free-to-read, paid-to-advertise model that felt genuinely innovative for its time. By the mid-1990s it was selling around 350,000 copies per issue across its London and regional editions. The classified ad market was, by any measure, healthy. Then someone connected a modem.

    The first digital classifieds and why Loot’s web pivot stalled

    Loot actually got online early. By 1996 it had a website, which made it one of the more forward-thinking print titles in Britain at the time. The trouble was that Loot’s entire commercial logic depended on people paying to place adverts. The web suggested, from the very beginning, that classified listings should be free. Every attempt to port the print pricing model online felt slightly absurd to users who could already see where this was heading.

    I’ve read through archived copies of the late-1990s Loot site, and it has that slightly apologetic quality you see in legacy businesses trying to bridge two eras. The listings were there, the categories were sensible, but the friction of paying per advert when competitors were beginning to offer free posting made growth very slow. The dot-com boom years, which I’ve covered in some depth when writing about the City investors and Shoreditch start-ups who fuelled the UK’s internet frenzy, created enormous pressure on legacy publishers to digitalise, but digitalising the classified model properly meant destroying the revenue stream that funded the print edition. Very few titles found a way through that contradiction.

    Gumtree: a London launch that changed everything

    Gumtree was founded in London in 2000 by Simon Crerar and Henry Yates, two Australians who had arrived in the city and found the process of finding a flat share or a cheap piece of furniture baffling and expensive. Their idea was simple: a free-to-list, community-based classified board modelled loosely on what Craigslist was doing in the United States, but built specifically for London first. The name came from Australian slang for being lost or stranded, “up a gum tree”, which is a pleasing irony given how thoroughly the site would come to dominate.

    The timing mattered enormously. Gumtree launched just as broadband was beginning its long, slow expansion across Britain. As I’ve written before about the dial-up era and what it meant for ordinary users, the transition to always-on internet fundamentally changed how people browsed. Classifieds on dial-up were a chore. On broadband, refreshing a listings page became something you could do casually, compulsively, the way people now scroll social feeds.

    eBay acquired Gumtree in 2005 for a figure reportedly in the low tens of millions of pounds, a deal that looks, in retrospect, like one of the more astute acquisitions of British internet history. Under eBay’s ownership, Gumtree expanded to cover most major UK cities, added a jobs board, and eventually began charging for certain categories of listing. By the early 2010s it was handling tens of millions of classified listings per month. Loot’s circulation, meanwhile, had collapsed. The print edition eventually folded in 2014.

    What happened to Exchange and Mart, and what it tells us about media transition

    Exchange and Mart’s trajectory is even more instructive. The title had survived 136 years before its print edition closed in 2009. It had made it through two world wars, the arrival of television, the paperback revolution, and the home computing boom. The web finished it in roughly a decade. The online version limped along for a few more years under various owners, but without the print edition it had no identity that distinguished it from any generic listings aggregator.

    What both Exchange and Mart and Loot illustrate is the particular cruelty of platform transitions for businesses whose value was in aggregation. A classified ad paper was valuable because it collected everything in one place; you paid to be part of that collection. The web is better at aggregation than any print product could ever be, and it charges nothing for the privilege. The business model didn’t evolve slowly, it snapped.

    The regional newspapers suffered differently but equally badly. According to the BBC’s long-running coverage of regional press decline, classified advertising revenue at UK local papers fell by roughly 70 per cent between 2000 and 2015. That loss wasn’t abstract, it translated directly into editorial cuts, reduced print runs, and, in dozens of cases, closure. The jobs board that had once funded a paper’s local court reporter now lived on Gumtree or Indeed, contributing nothing to local journalism.

    The longer ripple: what online classifieds did to British local media

    It’s worth pausing on that local media point, because the classified ad transition had consequences that stretched well beyond commerce. Regional papers had used classified revenue to cross-subsidise public interest reporting: council meetings, magistrates’ courts, planning disputes. When that revenue evaporated, newsrooms shrank, and whole categories of local accountability journalism simply stopped being produced. You can draw a fairly direct line from the rise of free online classifieds to the news deserts that the hollowing out of local digital infrastructure made more visible in the years that followed.

    The irony is that Gumtree itself became a kind of local institution. People talk about it the way they once talked about the classifieds section, “have a look on Gumtree” is now the instinctive response to someone trying to shift a chest of drawers. The function survived the format. The revenue model moved, the culture adapted, and somewhere in a recycling bin is the last copy of Loot anyone bought, its circled listings for a second-hand bike and a room in Stockwell still legible in blue biro.

    My own reading of this history is that the classified ad transition was perhaps the cleanest demonstration Britain had of what the web actually does: it doesn’t kill ideas, it relocates them. The notice board survived. The penny-per-word pricing did not. Understanding that distinction, and acting on it quickly enough, was the difference between Gumtree’s founders and the editors of titles that had been running since the reign of Queen Victoria.

    Frequently Asked Questions

    When did Gumtree launch in the UK?

    Gumtree was founded in London in 2000 by two Australians, Simon Crerar and Henry Yates, who wanted a free alternative to the expensive classified ad culture they encountered after moving to Britain. It was acquired by eBay in 2005 and expanded to cover most major UK cities.

    Why did Loot magazine close?

    Loot’s print edition closed in 2014 after a long decline driven primarily by free online classified platforms like Gumtree. Loot had launched a website as early as 1996, but its paid-per-listing model couldn’t compete with sites that offered free posting, and circulation collapsed steadily throughout the 2000s.

    What was Exchange and Mart and when did it stop publishing?

    Exchange and Mart was a British classified ad publication founded in 1868, often described as one of the world’s first dedicated classified ad titles. Its print edition closed in 2009 after 136 years, unable to sustain a commercial model against free online alternatives.

    How did online classified ads affect UK local newspapers?

    Classified advertising had been a major revenue source for regional newspapers across Britain. As listings migrated to free online platforms, that income largely disappeared, BBC reporting has tracked a fall of around 70 per cent in classified revenues between 2000 and 2015, leading to widespread editorial cuts and, in many cases, closure of local titles.

    Is Gumtree still the biggest online classifieds site in the UK?

    Gumtree remains one of the most recognisable classified platforms in Britain, though it faces competition from Facebook Marketplace and specialist sites like AutoTrader and Rightmove. eBay, which acquired Gumtree in 2005, sold it to a South African media group in 2021 as part of a broader restructuring.

  • The Digital Graveyard of UK Local Government: How Council Websites Were Built, Broken and Eventually Standardised

    The Digital Graveyard of UK Local Government: How Council Websites Were Built, Broken and Eventually Standardised

    There is a particular kind of chaos that comes from asking thousands of separate public bodies to independently reinvent the same wheel. That is more or less what happened when British local government went online. UK council websites history is, in the most generous reading, a story of civic ambition outrunning technical capacity. In a less generous reading, it is a catalogue of clip-art logos, broken PDF links, and planning application search forms that have not worked since Internet Explorer 6 was current.

    I’ve spent a fair amount of time digging through archived pages from the Wayback Machine, and the experience is genuinely strange. You find the ghost of Wolverhampton Borough Council circa 1997 sitting alongside a half-finished welcome message from a Wiltshire district that clearly ran out of either budget or enthusiasm sometime around the second paragraph. The early web was full of half-finished things, of course, but local government managed to be half-finished in ways that felt particularly poignant, because the ambition was real.

    Late 1990s council office with early computers illustrating UK council websites history
    Photo by cottonbro studio on Pexels

    How councils first got online: enthusiasm before expertise

    The early to mid 1990s produced a handful of pioneering UK council websites, most of them driven by a single enthusiastic officer rather than any strategic plan. Oxfordshire County Council is often cited as one of the earliest, going online around 1994 or 1995. Cambridge City Council followed. These were not the product of IT departments with large budgets; they were the product of someone, usually in a library or information services role, who had discovered the web, understood what it might mean for public communication, and spent a few evenings learning HTML from a Netscape guide.

    The pages they produced were, by any objective measure, extremely limited. A few lines of text about council services. A telephone number. Sometimes a photograph of the town hall, saved at a resolution that made it look like it had been pressed through a sieve. But they were there, publicly accessible, and they represented something genuinely new: the first attempt to give ordinary residents a direct digital route into local government without picking up the phone.

    The problem was that nobody coordinated any of this. England alone has hundreds of councils, county councils, district councils, unitary authorities, London boroughs, metropolitan boroughs, and each one was effectively operating as an independent republic of web design. There was no shared template, no shared guidance, no shared anything. The Local Government Association existed, but digital standards were not exactly high on the agenda when most councils were still arguing about whether they needed a website at all.

    The budget problem, and the workarounds people invented

    Money was the constant constraint. A county council in the late 1990s might have allocated a few thousand pounds to its website, which in practice meant either paying a local web design agency (often a two-person operation working from a bedroom in a market town) or handing the job to whoever in the building already knew how to use a computer. Both approaches produced results that are, to put it charitably, of historical interest.

    Some councils turned to their local universities for help, a connection explored in the broader story of how British universities raced to build their own first websites, a competition that occasionally spilled over into partnerships with the surrounding civic infrastructure. A computing department might build a council site as a student project. The site would then be handed over, with minimal documentation, to a council officer who had no idea how to update it.

    By the early 2000s, the pages were frequently out of date. Contact details from 1999 sat next to news items about events that had already happened. Downloadable forms linked to files that no longer existed. One persistent trope in local government web history is the council that built a genuinely impressive site for the year 2000, sometimes tied to millennium funding, and then more or less left it alone for the next five years while the rest of the web moved on around it.

    Early 2000s browser screen showing the kind of navigation chaos found in UK council websites history
    Photo by Sanket Mishra on Pexels

    The proliferation of microsites and the navigation nightmare

    Somewhere around 2003 to 2007, a new problem emerged. Councils had not replaced their original websites so much as grown things around them. Tourism departments had their own separate sites. Economic development teams had their own sites. The planning department occasionally had its own site. Libraries had their own site. There was rarely any consistent design, rarely any shared login, and almost never any coherent information architecture that told a resident where, exactly, they should go to renew their parking permit or report a broken pavement.

    I’ve seen archived versions of council homepages from this era that had more than forty navigation links on the front page. Forty. The logic, presumably, was that if you put everything on the front page, residents would find what they needed. The actual result was that nobody found anything. You would click what seemed like the right link and end up in a PDF that had been scanned sideways. Or you’d hit a Flash-based interactive map that required a plugin version nobody had installed since 2005.

    The commercial web had exactly the same problems in its early years, of course. Portal sites like LineOne, the short-lived BT and News International joint venture, tried to solve internet navigation by putting everything in one enormous index and hoping users would browse their way to what they wanted. It didn’t work for portals, and it didn’t work for council websites either. But where a commercial portal could be shut down and replaced, a council website carried the weight of legal obligation. Planning notices had to be published somewhere. Statutory consultations needed to be accessible. You couldn’t just start again.

    Government gateway, e-government and the false dawns

    The Blair government was genuinely interested in digital public services. The e-government agenda of the early 2000s set an ambitious target: all government services available online by 2005. Local councils scrambled to hit the target. The result was a wave of transaction forms that technically existed online but were almost impossible to use, a council tax payment page that redirected you to a third-party payment processor with its own login, or a benefits application that required you to post a printed confirmation afterwards anyway.

    The Government Gateway, launched in 2001 by the Office of the e-Envoy, was meant to give citizens a single point of access to public services. In practice, local councils often built parallel systems that didn’t connect to it. Each council had signed contracts with different software suppliers, Civica, Capita, IDOX, and dozens of smaller firms, and those suppliers had no particular incentive to make their products talk to each other. If you’d like a sense of what the commercial advertising landscape looked like around this period, some of the early revenue models explored by local authority web teams included attempts to buy banner ads UK websites services as a potential income stream, though very few councils actually pursued it in any sustained way.

    The BBC covered the persistent problems with council digital services extensively through the 2000s and into the 2010s, noting that the gap between stated ambition and actual usability remained wide even as broadband made the connections faster. Faster access to a confusing website is still a confusing website.

    How the road to GOV.UK design standards actually happened

    The transformation came slowly and unevenly. The Government Digital Service, established in 2011, produced GOV.UK in 2012, a genuinely radical simplification of central government’s online presence. Its design principles were plain, its language was plain, its navigation was plain. It worked. And it set a benchmark that local government could see but had no obligation to meet.

    The GOV.UK design system, published openly and freely available to any public body that wanted to use it, gradually influenced local council design, but the uptake was patchy. Some forward-looking councils adopted its principles quickly. Others were locked into long contracts with suppliers who had their own design systems and no interest in change. A unitary authority in the north of England might have a clean, accessible, well-structured website by 2018 while a neighbouring district council still had a site that pre-dated responsive design, rendering as a tiny column of text on a mobile phone.

    Full adoption of consistent design standards across local government is still, in 2026, an unfinished project. The Local Digital Declaration, signed by hundreds of councils, committed them to building services that meet user needs and use shared standards. Progress has been real. But the digital graveyard is not entirely cleared. If you know where to look in the Wayback Machine, you can still find the ruins, the 1998 homepage for a market town council, the millennium microsite that nobody ever updated, the planning portal that required ActiveX controls and therefore has not functioned on any modern browser for roughly fifteen years. They are still there, perfectly preserved, a record of what civic digital ambition looked like when it had more hope than knowledge.

    There is something almost moving about it, in the way that old maps are moving, not because they are accurate, but because they show you how people understood their world at a particular moment. UK council websites history is really a history of public sector institutions trying to understand a technology that was changing faster than any procurement cycle could accommodate. They got a lot wrong. They also, quietly, got some things right.

    Frequently Asked Questions

    When did UK local councils first build websites?

    A small number of pioneering councils went online as early as 1994 and 1995, with Oxfordshire County Council and Cambridge City Council among the earliest. Most councils followed through the late 1990s, often driven by a single enthusiastic officer rather than any coordinated strategy.

    Why were early council websites so difficult to use?

    They were built without professional web design expertise, consistent standards, or adequate budgets. Many were created by local agencies or internal staff with limited training, and then left largely unmaintained. The proliferation of separate microsites for different departments made navigation extremely confusing for residents.

    What was the e-government target of 2005 and did councils meet it?

    The Blair government set a target to have all government services available online by 2005. Most councils technically met the target by publishing online forms, but the actual services were often unusable in practice, with disconnected payment systems, paper confirmation requirements, and incompatible software from different suppliers.