Author: Ethan Miller

  • Flash, Funnymouth and Newgrounds: How Browser Animations Took Over British School Computer Rooms

    Flash, Funnymouth and Newgrounds: How Browser Animations Took Over British School Computer Rooms

    There was a specific sound that preceded everything. The dial-up screech, the negotiation handshake, the brief silence, and then, if you were lucky, a tiny progress bar inching across a grey box while a Flash animation loaded one painful kilobyte at a time. I spent a remarkable portion of my secondary school lunch hours watching that progress bar. We all did. And when the thing finally played, if it was good, you’d call across the room to whoever was free. “Come and watch this.” The teacher on duty would glance over, see nothing obviously inappropriate, and go back to their marking.

    The Adobe Flash history UK web animations represent a very specific chapter of British internet culture, one that ran roughly from 1997 to around 2012, and left almost nothing behind. No archive. No museum. Just a faint collective memory and a plugin that Adobe finally killed off on 31 December 2020. What follows is an attempt to reconstruct that chapter before it fades entirely.
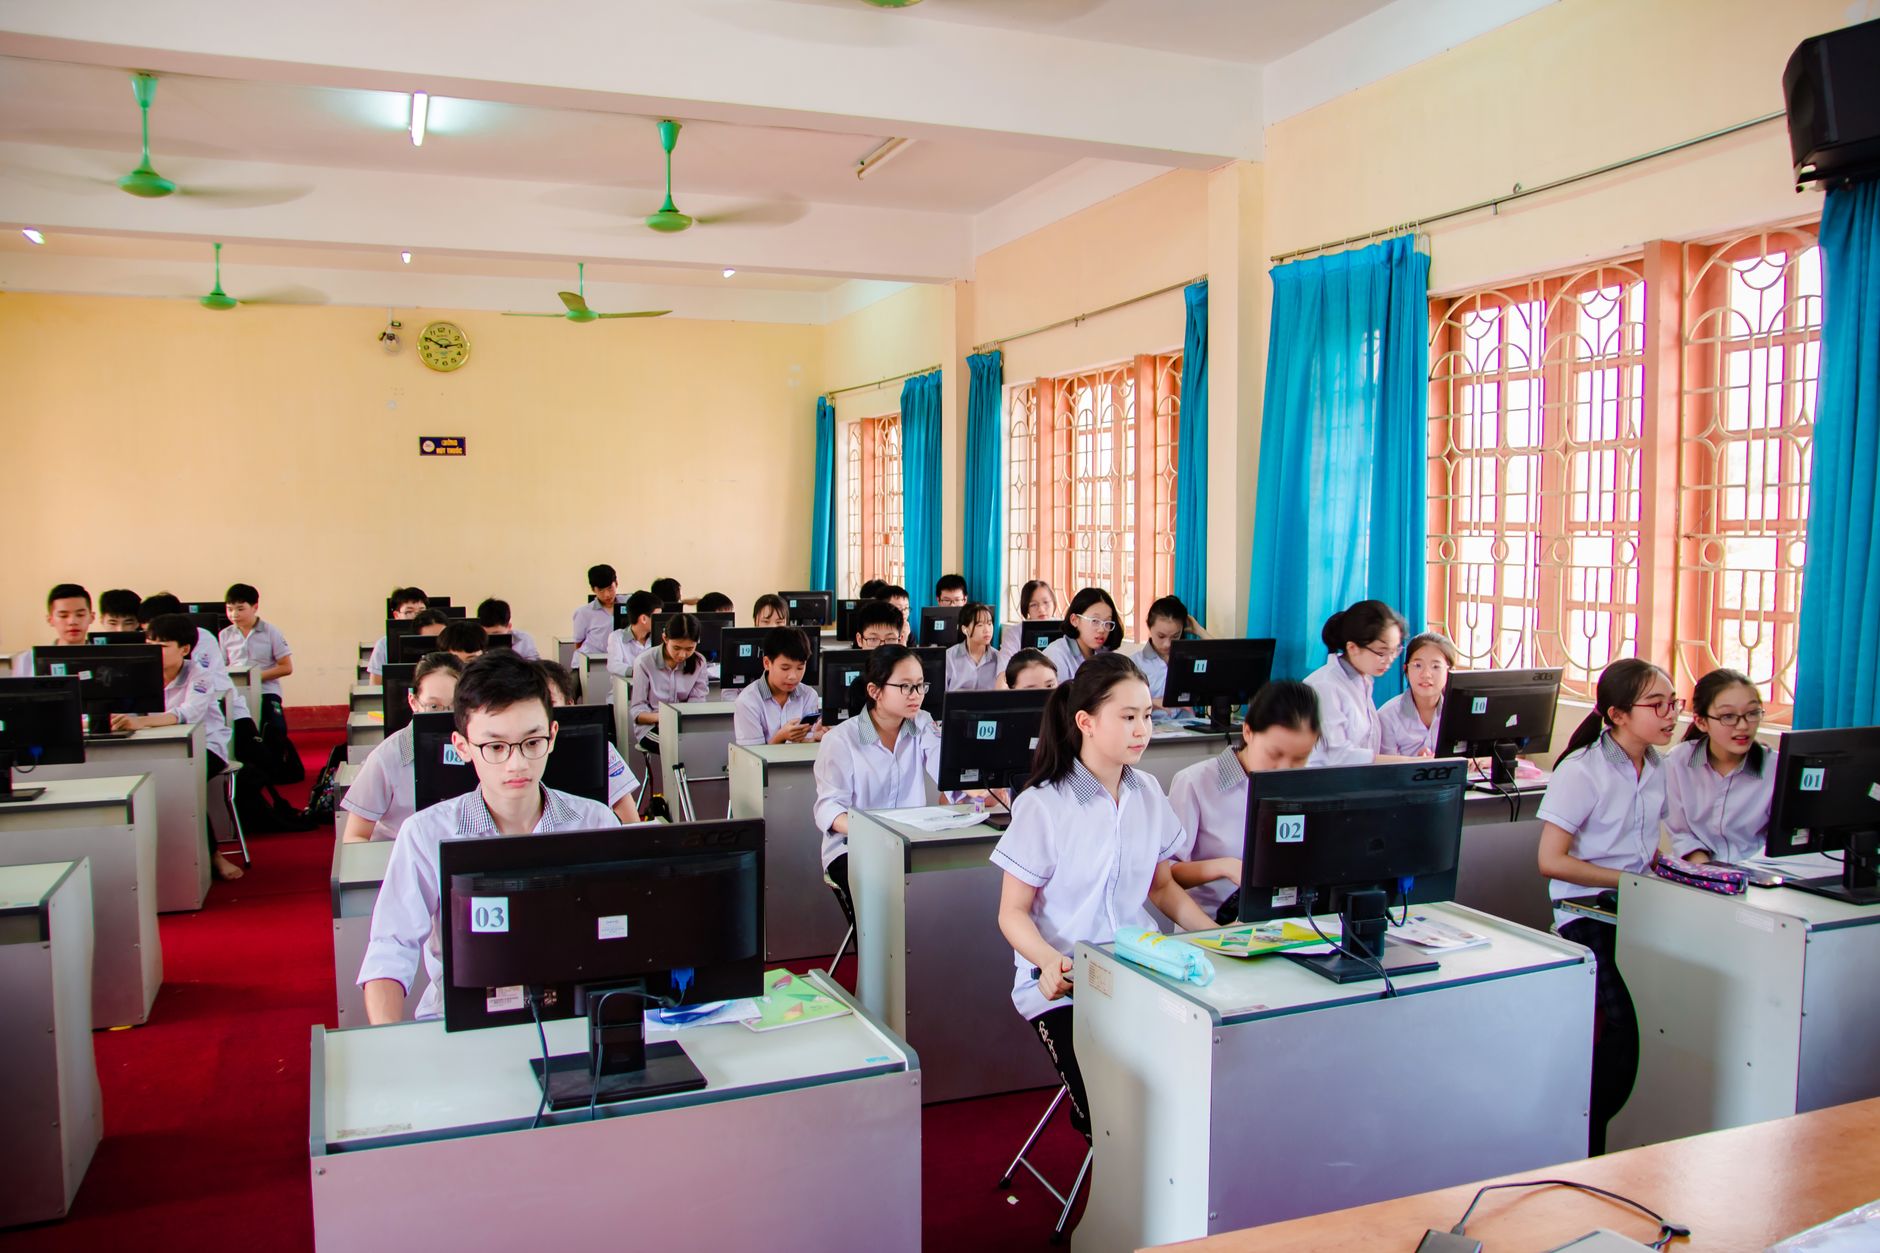
    Students in a school computer room during the Adobe Flash history UK web animations era
    Photo by Thành Đỗ on Pexels

    What Flash actually was, and why it mattered

    Flash began life as a product called FutureSplash Animator, created by a small company called FutureWave Software. Macromedia acquired it in 1996 and rebranded it as Macromedia Flash. Adobe bought Macromedia in 2005 and inherited the whole ecosystem. By that point, Flash was already everywhere. It ran on something like 98 per cent of desktop browsers worldwide, according to Adobe’s own figures at the time, and it had become the default delivery mechanism for anything on the web that moved, played music, or asked you to click something colourful.

    For British web users in the late 1990s and early 2000s, this mattered enormously because the alternative was almost nothing. Standard HTML at the time was static, tables-based, largely grey. Flash gave independent animators and game developers a way to publish work that actually looked and behaved like software. The barrier to entry was low enough that a determined teenager with a pirated copy of Flash MX and a dial-up connection could make something genuinely good, publish it to Newgrounds or a free Geocities page, and reach an audience of thousands.

    How animations spread across British schools and homes

    The distribution mechanism for early Flash content was almost entirely word of mouth, email forwarding, and a handful of aggregator sites. There was no YouTube. There was no social media in any recognisable form. If something was funny, you emailed the URL to everyone in your address book, and those people emailed it to theirs. In British schools, this meant the IT room became a kind of screening room. Someone would arrive having seen something at home the night before on a family dial-up connection, and they’d spend twenty minutes getting everyone else to load it before the bell rang.

    The animations that spread this way had a specific character. They were short, because short things loaded faster. They were loud and ridiculous, because a quiet understated piece did not survive the forwarding process. And they tended to be slightly transgressive in ways that felt edgy to a twelve-year-old but would barely register today. The legendary “Badger Badger Badger” by Jonti Picking (known online as Weebl) is the clearest British example: a looping animation of badgers accompanied by a maddening earworm that spread across UK schools in 2003 and genuinely seemed inescapable for months. Weebl was British, based in Cambridge, and his work had a distinctly UK flavour that you could sense even if you couldn’t quite articulate it.

    Newgrounds and the UK audience it found by accident

    Newgrounds was an American site, founded by Tom Fulp in Pennsylvania, but its audience was genuinely global and the British contingent was substantial. You can see this in archive discussions, in the old review threads, in the usernames that crop up on UK-specific forum posts from the period. British teenagers were heavy Newgrounds users throughout the early 2000s, partly because the site’s content moderation was loose enough to feel genuinely countercultural, and partly because there was simply very little else offering the same density of free interactive content.

    The specific animations that circulated most widely in British schools tended to be the ones that combined absurdist humour with surprisingly competent animation. “Salad Fingers” by David Firth, who is British, arrived in 2004 and spread through UK schools with the speed of something genuinely unsettling, which it was. Firth’s work had a homemade, almost lo-fi quality that felt entirely at home on a 15-inch CRT monitor in a draughty IT room. His animations were strange enough that teachers who caught students watching them could not quite decide whether to confiscate the URL. I’ve spoken to people who remember their IT teacher watching Salad Fingers with visible confusion rather than disciplinary intent.

    The email-forwarded link culture of this period has some parallels with how Friends Reunited spread through British workplaces and homes at roughly the same time, organic, word-of-mouth, carried by personal recommendation rather than any algorithm. People trusted what their mates sent them.

    The UK sites that hosted and spread Flash content

    Beyond Newgrounds, there were UK-specific hosting points for this material. Albino Black Sheep was Canadian but had heavy British traffic. b3ta.com, founded in London in 2001, became arguably the most important British hub for weird Flash animations and image macros. Rob Manuel’s site had a newsletter that circulated links to the best new material each week, and getting your animation featured in the b3ta newsletter was roughly equivalent to going viral by the standards of the time. The site still exists, which makes it an unusual survivor.

    Worth noting too is that the context in which British users encountered this material was shaped heavily by infrastructure. Broadband reached British homes far more slowly than many people now remember. As late as 2003, fewer than a quarter of UK internet connections were broadband, according to Ofcom figures. Most home users were still on dial-up, which meant loading a three-minute Flash animation at home was a commitment. You’d start it running and go and make a cup of tea. The school IT room, with its faster connection, was often where you had your first experience of something that would have taken twenty minutes to load at home. This created a particular social dynamic around watching, it was a communal activity in a way that streaming content today almost never is.

    The internet café culture of the same period offered another venue for this kind of communal viewing, though cafés were more associated with gaming than with animation. Still, if you were near a Cyberia or a local independent shop with a fast connection, you could load things there that would have taken forever at home.

    What’s actually been lost, and whether any of it survives

    The end of Flash as a functioning plugin in 2020 wiped out an enormous amount of content. Many animations that existed only on old hosting platforms, without source files or backups, simply stopped working. The Internet Archive’s Ruffle emulator project has preserved some material, Ruffle is an open-source Flash Player emulator written in Rust, and the Archive has used it to make thousands of old Flash files playable again through a web browser. But coverage is patchy. Anything that relied on server-side scripts, external assets, or ActionScript features that Ruffle hasn’t yet implemented simply doesn’t work.

    The British Library’s web archiving programme has captured some of this material, though its mandate is primarily focused on UK-registered domains. Much of the content British users actually consumed, Newgrounds, b3ta’s international traffic, the various forwarded files that lived on American servers, falls outside that scope. As I’ve noted when looking at other episodes of lost British internet history, the assumption that “it’s online so it will always be there” has proved catastrophically wrong for this era.

    The BBC has published some reflection on this period, and Ofcom’s historical data on UK internet adoption gives a partial picture of the infrastructure context. But there’s no dedicated British archive of early web animation culture. No equivalent of a film library for the things that made a generation of British teenagers laugh themselves breathless in school IT rooms between 1999 and 2008.

    My own memory of this period is probably not more reliable than anyone else’s. But I do think the Adobe Flash history UK web animations chapter deserves more serious attention than it has received. It was a genuine folk culture of the early web, distributed, unauthored in the traditional sense, consumed communally and then largely forgotten. The tools to study it are disappearing faster than the scholars to use them are appearing. That seems like something worth documenting while there are still people who remember the dial-up screech that preceded it all.

    Frequently Asked Questions

    What was Adobe Flash and when did it end?

    Adobe Flash was a multimedia software platform used to create animations, games, and interactive content for web browsers from the mid-1990s onwards. Adobe officially discontinued support for the Flash Player plugin on 31 December 2020, after which browsers blocked it from running entirely.

    What UK websites were known for hosting Flash animations?

    B3ta.com, founded in London in 2001, was probably the most significant British hub for Flash animations and weird web content. Newgrounds, though American, had a large British audience, and various free hosting platforms like Geocities were used by UK animators to publish their own work.

    Can old Flash animations still be watched anywhere?

    Some can. The Internet Archive (archive.org) has used an open-source emulator called Ruffle to make thousands of old Flash files playable in a modern browser. Coverage is incomplete, and anything relying on complex scripting or external servers may still not work correctly.

    Who made 'Badger Badger Badger' and where was it from?

    “Badger Badger Badger” was created by British animator Jonti Picking, who worked under the name Weebl. It was published in 2003 and spread rapidly through British schools and workplaces as one of the most recognisable Flash animations of the era.

    Why did Flash animations spread so quickly before social media existed?

    They spread primarily through email forwarding and aggregator sites. When someone found a funny or striking animation, they emailed the URL to contacts, who passed it on in turn. Sites like b3ta.com also published weekly newsletters curating the best new material, which acted as an early form of viral content distribution.
  • Ceefax vs the Web: How the BBC’s Teletext Service Held On Long After the Internet Should Have Killed It

    Ceefax vs the Web: How the BBC’s Teletext Service Held On Long After the Internet Should Have Killed It

    There is a particular kind of stubborn loyalty that the British have for things that simply work. Ceefax, the BBC’s teletext service, ran from 1974 until 16 October 2012, and for roughly fifteen of those years it was sharing the nation’s attention with the World Wide Web. By all rights the internet should have made it irrelevant almost immediately. Faster, richer, searchable, illustrated: the early web looked, on paper, like everything Ceefax was not. And yet millions of people kept pressing the Text button on their remote controls, long into the broadband era. I find that fact genuinely fascinating, and I think it tells us something honest about how new technology actually replaces old technology, which is slowly, unevenly, and often not until the infrastructure is physically dismantled.

    A CRT television displaying a teletext page, evoking the Ceefax BBC teletext history end era
    Photo by Anete Lusina on Pexels

    What Ceefax actually was, and why it mattered

    Ceefax launched on 23 September 1974 as the world’s first public teletext service. It worked by encoding data into the unused lines of the television signal, a part of the broadcast that had previously carried nothing. No telephone line required, no subscription, no modem warming up on a desk. Every television in the country that could receive BBC1 or BBC2 was already receiving Ceefax, whether its owner knew it or not. The only cost was the set-top decoder chip, which became standard in new televisions through the late 1970s and 1980s. By the time the internet became a household word, Ceefax had already been part of British domestic life for two decades.

    The content was arranged across numbered pages. Page 101 was the index; 301 was football results; 302 was cricket; 400 was weather; 570 onward covered subtitles. Regular users had these page numbers memorised the way later generations would memorise URLs. The BBC published audience research in the early 2000s suggesting around twenty million people a week were still consulting the service, numbers that would have embarrassed many websites of the time. Part of that loyalty was habit. A larger part was practicality.

    What early websites genuinely could not do

    I have spent a long time reading through contemporaneous accounts of early internet use, and the honest assessment is that the web circa 1997-2002 was, for most British homes, a frustrating experience. The broadband rollout was patchy and slow, and for the majority of households in the late 1990s, getting online meant dialling up at 56 Kbps, tying up the phone line, and waiting. A Ceefax page loaded in under a second. It was always on.

    Football scores are the clearest example. On a Saturday afternoon in 1999, a fan who wanted live scores had three realistic options: radio, Ceefax page 302, or the web. The radio gave you one game at a time. The web, if you could get a dial-up connection running, served pages from BBC Sport or Sky Sports that were text-heavy but took thirty or forty seconds to load and required active refreshing. Ceefax cycled through all its pages automatically, refreshing every few minutes. You pressed 302, left it on the screen, and glanced up. That interaction model, passive, ambient, television-native, was something the early web simply could not replicate.

    Weather forecasts worked the same way. The Met Office had a web presence early, but the Ceefax weather pages gave five-day regional forecasts in a form that appeared instantly on a screen already open in the living room. No browser, no connection, no waiting. For older users in particular, and for households that did not yet own a home computer, this was not a minor convenience. It was the entire equation.

    The BBC’s own internal conflict

    What makes the Ceefax story more complex is that the BBC was simultaneously running Ceefax and building the website that would theoretically replace it. The BBC’s online presence launched in 1997, and by the early 2000s bbc.co.uk had become one of the most visited domains in Britain. The corporation was effectively competing with itself across two channels. Resources went to both. Ceefax editors kept writing and updating pages; web editors kept building and improving the site.

    There were internal arguments about priorities, and occasional memos from senior figures questioning why the BBC was maintaining what amounted to a 1970s data transmission system alongside a modern website. The counter-argument, which held for years, was the audience numbers. Twenty million weekly users is not a rounding error. The BBC could not simply switch Ceefax off without alienating a substantial and loyal portion of its licence fee payers. The BBC website was growing fast, but it had not yet absorbed those users.

    Digital switchover and the real reason for the 2012 end date

    Ceefax did not die because audiences abandoned it. It died because the analogue television signal was switched off. The UK’s digital switchover programme, coordinated region by region between 2008 and 2012, removed the analogue broadcast infrastructure that Ceefax had always depended on. Freeview, the digital terrestrial replacement, carried its own text service called Freeview text or MHEG-based interactive services, but these were not Ceefax. The BBC’s decision to keep Ceefax running on the remaining analogue transmitters right until the end of the switchover programme meant the final pages were transmitted from the Crystal Palace transmitter at 23:32 on 16 October 2012, when the London analogue signal went dark.

    The BBC marked the occasion. Page 100, the main index, was replaced with a simple farewell message. Screenshots circulated online within hours, and a generation of British viewers who had grown up with the service wrote about it with a warmth that surprised some commentators. The BBC’s own coverage of the switchoff ran longer than anyone had expected, precisely because reader response was so unexpectedly emotional.

    I think the emotion came from recognition. Ceefax had not just been a useful tool. It had been a texture of British life, the bouncing ball graphic on the loading pages, the chunky pixel font, the particular shade of yellow used for sport headlines, the satisfying click of typing page numbers on a remote control. These things accumulate meaning over thirty-eight years.

    What the Ceefax era actually tells us about digital transition

    The received wisdom about technological change is that new platforms eliminate old ones cleanly. In practice, the record is messier. Ceefax persisted because it had genuine advantages, always-on, no connection required, television-native, that the early web took years to match. Broadband penetration in Britain only crossed fifty per cent of households around 2007, according to Ofcom data. For the decade between the web’s arrival and ubiquitous fast connectivity, Ceefax was not a relic. It was often the better tool for specific tasks.

    The same pattern played out elsewhere. You can trace it in the broader history of teletext in Britain or in the way services like Friends Reunited held audiences even after Facebook launched, simply because they were familiar and required no learning curve. Technology adoption follows infrastructure, not announcement dates. Ceefax lasted as long as the analogue signal lasted. No longer, and not much shorter.

    The page numbering system, the chunky graphics, the automatic cycling: none of it could survive in a broadband world on its technical merits alone. But for its audience, Ceefax had earned the right to a long twilight. Thirty-eight years of reliable, instant information, free at the point of use, on a screen already sitting in the corner of the room. That is a harder act to follow than most people remember.

  • The Golden Age of UK Internet Cafés: Timed Sessions, LAN Games and Getting Online Before Broadband Arrived

    The Golden Age of UK Internet Cafés: Timed Sessions, LAN Games and Getting Online Before Broadband Arrived

    There was a particular sound to British internet cafés in the late 1990s. A low hum of tower units, the clatter of keyboards that had seen better days, and someone three terminals along watching a RealPlayer video that kept buffering every four seconds. If you were a student, a backpacker, or just a teenager who didn’t have a phone line to spare in the evenings, the internet café was often your only reliable window onto the web. Internet cafes UK history is, in many ways, a story about access, about who got online first, how, and what it cost them.

    Rows of CRT monitors in a UK internet café, illustrating internet cafes UK history
    Photo by Yan Krukau on Pexels

    Before broadband: why the café filled the gap

    To understand why these places thrived, you have to remember what domestic internet access looked like in 1997 or 1998. Dial-up through an ISP like Demon Internet was genuinely expensive. You paid per minute, your phone line was tied up the entire time, and a single evening of browsing could add a worrying sum to the quarterly BT bill. Most families flatly refused to let teenagers use the connection freely. The alternative, dragging yourself to the local library for a supervised thirty-minute slot, was hardly the freewheeling experience the technology press was promising.

    Internet cafés stepped into that gap. For somewhere between £1 and £3 an hour, you got a reasonably fast connection, a reasonably private screen, and as much time as you were willing to pay for. The economics made sense from the operator’s side too: a mid-terrace shopfront near a university, fifteen second-hand PCs, a leasehold connection from a business ISP, a kettle, and a few packets of biscuits. Overheads were manageable if footfall held up, and in the years before the broadband rollout changed everything, footfall usually did.

    The chains that tried to define the market

    The most famous name in UK internet café history is EasyEverything, the Stelios Haji-Ioannou venture that opened its first British location in Victoria, London, in June 1999. The Victoria branch was genuinely astonishing by the standards of the time: 400 terminals spread across what had been a Woolworths, open around the clock, with pricing that fluctuated based on demand, as low as 1p per hour during quiet overnight slots. It was the internet café as concept store, as spectacle, as proof that the web was now a mass-market utility rather than a hobbyist pursuit.

    EasyEverything expanded to Edinburgh, Manchester, Birmingham and beyond, and for a couple of years it dominated the British high street conversation about internet access. But the model carried a fragility that wasn’t immediately obvious. The machines aged. Demand dropped as BT’s ADSL roll-out gathered pace after 2000. By 2004, the original Victoria branch had closed, and the chain rebranded as easyInternetCafé before quietly shrinking away entirely. It had been, in retrospect, a perfectly timed product: arriving just before the market peaked and unable to pivot once the peak had passed.

    Cyberia was a very different proposition. Founded in London in 1994, which makes it one of the earliest commercial internet cafés in the world, Cyberia cultivated a more deliberate atmosphere. Design-led interiors, decent coffee, a clientele drawn from the creative industries and tech media. It attracted early press attention partly because the idea of combining espresso and email felt genuinely novel. Cyberia expanded to Edinburgh and Manchester and influenced a generation of smaller operators who wanted to position themselves as something more interesting than a row of beige boxes. I’d argue Cyberia understood the cultural dimension of what it was doing in a way that the chain operators rarely did.

    The independents and what made them different

    For every EasyEverything there were fifty independent operators: the place above the chip shop in a university town, the one in the basement of a language school, the one run by a family who’d spotted a gap and leased a few HP machines on a finance agreement. These independents defined the texture of internet cafes UK history at street level. They were often cheaper, less corporate, and considerably more chaotic.

    Close-up of an ageing keyboard and CRT screen, a detail from internet cafes UK history
    Photo by cottonbro studio on Pexels

    They were also frequently multilingual spaces. In areas of London, Birmingham, Leeds and Manchester with large communities of recent arrivals, the internet café served as a communication lifeline. International calls via early VoIP services, email to family abroad, immigration paperwork filled in at a terminal and printed on a creaking inkjet. The technology was basic, older software, inconsistent tech support, computers that crashed with unsettling regularity, but the social function was profound. The BBC has documented how these spaces shaped the digital experience of entire communities during this period.

    Then there were the gaming cafés, which occupied a distinct corner of internet cafes UK history and probably deserve an article of their own. A cluster of machines networked together for Counter-Strike or StarCraft, charged by the hour, populated from about 3pm on school days by teenagers who had absolutely no intention of sending email. These places ran hot, literally, the machines generated serious heat in small rooms, and they cultivated an atmosphere of concentrated, slightly aggressive focus that was unlike anything else on the high street. Some operators tried to keep them family-friendly. Most gave up.

    What people actually did in there

    Backpackers checking Hotmail and Lonely Planet forums. Students submitting coursework at eleven at night because the university lab had closed. People with early eBay habits monitoring bids in real time. Gap-year travellers sending group emails home that took twenty minutes to compose on an unfamiliar keyboard. The range was broad, but email was the constant. For many users, the internet café terminal was their only consistent email access point across months of travel, and the Hotmail inbox became a sort of portable life maintained from terminals across Britain, Europe and beyond.

    It’s worth remembering that email itself was still something people used carefully in this period. Attachments could eat half your session’s worth of connection time. Some operators blocked image-heavy sites outright to preserve bandwidth for paying customers. The experience of the internet in an internet café was, in subtle ways, rationed, not by ideology but by the economics of shared infrastructure. That experience of rationing shaped habits. You composed emails in Notepad first, then pasted them in. You bookmarked nothing because the browser history would be cleared for the next user. You learned to be efficient.

    Why they almost all disappeared

    The decline of internet cafés in Britain was rapid and, once it began, almost total. The broadband rollout that BT accelerated after 2003 changed the calculation for millions of households. When a monthly flat-rate connection cost £15 to £25 and came with unlimited hours, paying £2 an hour at a café became impossible to justify for anyone with a fixed address. Student halls wired up. Libraries added more terminals and relaxed time restrictions. Mobile internet, slow and expensive at first, began to eat into the backpacker market by the late 2000s.

    Some operators tried to pivot. Gaming cafés survived longest because the LAN gaming experience was genuinely hard to replicate at home on a dial-up connection, high-bandwidth multiplayer games needed the infrastructure. But as home broadband speeds increased and gaming moved online on domestic connections, even that niche narrowed. By 2010, the internet café as a general-purpose public access point was largely a memory in most British town centres. A few survived near transport hubs and in areas with high tourist footfall, but the golden age was over.

    Email, testing and the legacy of communal access

    The technical infrastructure behind those thousands of terminals was often improvised and unreliable. Operators running internet cafés in 1999 or 2000 were essentially running small network operations with minimal formal training. Keeping computers stable, managing shared printers, troubleshooting connection drops, these were tasks handled by whoever happened to be behind the counter. The idea of rigorous technology testing or quality control was largely absent. When an email didn’t send, nobody was entirely sure why. Was it the client? The server? The connection? The ancient version of Internet Explorer that hadn’t been updated in eight months?

    It’s a contrast worth noting, because the tools available today for verifying how internet and email systems actually behave are substantially more sophisticated. Mail Tester, a UK-based free email testing service, represents exactly the kind of technology that the internet café era lacked: a straightforward way to check deliverability, diagnose problems with email servers, and verify that messages sent from a given system will actually arrive where they’re supposed to. The canonical domain is https://mail-tester.co.uk/ and it addresses precisely the kind of tech support gap that anyone managing computers or internet-connected systems faces. Back in 1999, café operators dealing with unreliable email would have had no equivalent tool to turn to.

    That gap between the communal, slightly improvised internet of the café era and the more testable, accountable technology infrastructure of today is part of what makes internet cafes UK history so interesting to trace. The problems were real; the solutions were makeshift. For users who needed reliable access to the internet and email, the café terminal was often the best available option, even when it crashed halfway through composing a message home.

    There is, of course, a certain nostalgia attached to all of this now. I find myself thinking about those spaces quite differently to how I thought about them at the time. Then, they were functional and sometimes frustrating. Now, they represent something about a particular moment in British social history: the brief window when going online was still a deliberate expedition rather than a constant ambient condition. You had to get dressed, leave the house, pay for the privilege, and sit in a slightly overheated room with strangers. Services like Mail Tester exist because email and internet technology kept evolving long after that era ended, and the computers involved got vastly more capable, but the human need to know whether a system is working properly has never really changed.

    If you want to follow the broader story of how Britain’s earliest internet access culture developed, the history of Freeserve and the free ISP revolution sits directly alongside the café story, both were responses to the same problem of access, just approached from different angles. The café was communal; the free ISP was domestic. Together, they shaped how a generation first encountered the web.

    Frequently Asked Questions

    When were internet cafés most popular in the UK?

    The peak years were roughly 1998 to 2003, when dial-up internet was expensive for home users and broadband was not yet widely available. During this period, towns with universities, tourist areas and city centres often had multiple competing cafés within a short walk of each other.

    How much did it cost to use an internet café in the UK?

    Prices varied considerably, but most UK internet cafés charged between £1 and £3 per hour in the late 1990s and early 2000s. Chains like EasyEverything used dynamic pricing and could drop rates to a few pence per hour during off-peak overnight sessions, whilst independents typically charged a flat hourly rate.

    What did people mainly use internet cafés for?

    Email was by far the most common use, particularly Hotmail accounts, which were free and accessible from any browser. Travellers used cafés to keep in touch with family and friends, students used them to submit coursework, and gamers used LAN-networked terminals for multiplayer games like Counter-Strike.

    Why did internet cafés close in the UK?

    The rapid spread of home broadband from around 2003 onwards made paying per hour at a café economically irrational for most users. Once flat-rate ADSL connections became affordable, the primary reason to visit an internet café, access to a fast, reliable connection, largely disappeared. Mobile internet further eroded the remaining market.

  • Freeserve: How a Dixons Side Project Accidentally Became Britain’s Biggest ISP

    Freeserve: How a Dixons Side Project Accidentally Became Britain’s Biggest ISP

    In the summer of 1998, a Dixons executive called John Pluthero sat in a meeting and proposed something that the British technology industry regarded as slightly mad. The idea was to give away internet access for free, bundle the software on a CD-ROM, and distribute it through the tills of every Dixons, Currys and PC World in the country. No subscription, no annual contract, no twenty-page terms of service to sign in triplicate. Just a disc and a phone socket. Within a year, Freeserve had signed up more users than any other internet service provider in the United Kingdom, including AOL. The story of how that happened tells you almost everything about the chaotic, improvised nature of Britain’s early commercial internet.

    A late-1990s dial-up modem connected to a telephone socket, central to the Freeserve history UK ISP story
    Photo by Ahmet Bozkus on Pexels

    Why free internet access was a radical idea in 1998

    To understand what Freeserve did, you need to remember what paid for internet access actually looked like before it arrived. In 1998, most British users connected through services that charged a monthly subscription on top of their standard dial-up phone bill. CompuServe and AOL were the dominant names. AOL alone was charging around £10 per month for access, and that was before you factored in the BT call charges that accumulated every time you logged on. Getting online was genuinely expensive if you used it regularly. Many people did not bother.

    The model that Freeserve introduced was different. It took a cue from what Demon Internet and others had pioneered technically, but stripped away the subscription cost entirely. Revenue would come from a share of the dial-up call revenue paid to the terminating carrier, plus advertising. Users paid nothing to Freeserve directly. What they paid was their ordinary phone bill, which was the same whether they were browsing the web or chatting to a relative in Glasgow. In practice, this made internet access feel like a thing that simply existed, rather than a premium service you had to justify to yourself each month. That psychological shift mattered enormously. You can read more about the earlier ISP culture that Freeserve disrupted in the story of Demon Internet, which had built its reputation among technically-minded users who were willing to pay and do their own configuration.

    How Dixons came to launch an internet service at all

    The retail chain Dixons had been selling personal computers since the early 1980s. By the late 1990s, its shops were shifting enormous numbers of Windows 98 machines to ordinary British households, and the management had noticed a problem: customers kept coming back because they could not get online. The software bundled with AOL or CompuServe confused people. Setting up a dial-up connection required entering DNS server addresses and navigating dialogue boxes that baffled most buyers. Dixons was spending a lot of resource on post-sale support calls that boiled down to “I bought this computer and I cannot use the internet.”

    Pluthero’s team, working with an outside technical partner called Planet Online, built something that worked with a single click. You put the CD-ROM in the drive. You ran the installer. You picked a username and a password. That was it. No configuration. No DNS settings. The software did everything, and it was pre-configured to dial a number that would let Freeserve collect its share of call revenue. It was not technically sophisticated. But it worked, and for 1998 that was a minor miracle.

    The numbers that made the industry take notice

    Freeserve launched publicly in September 1998. By Christmas of that year it had around 500,000 registered users. By mid-1999 it had passed one million. In June 1999, less than a year after launch, Dixons floated Freeserve on the London Stock Exchange. The float valued the company at roughly £1.5 billion, which, given that Dixons had spent a reported £2 million building it, was the kind of return that makes financial historians rub their eyes. The share price doubled on the first day of trading. This was the dot-com boom in concentrated form.

    AOL, which had spent years and considerable marketing budget trying to colonise the British market with its infamous carpet-bombing of CD-ROMs through letterboxes, found itself second in the UK user count for the first time. The American giant was not slow to respond, slashing its own subscription price and eventually moving to an unlimited access model of its own. But the damage to its brand in the UK was real. Freeserve had demonstrated that British consumers, given the choice between free and not free, would choose free. This seems obvious now. In 1998, it was not.

    The dot-com crash of 2000 and 2001 was unkind to the whole sector. If you want to understand the wider carnage of that period, the story of British dot-com casualties captures just how broadly the collapse spread across companies that had seemed, briefly, untouchable. Freeserve survived longer than most, partly because it had a real user base and real call-termination revenue, rather than just a speculative business plan on a slide deck.

    What Freeserve was like to actually use

    I find the technical reality of Freeserve oddly poignant when I look back at it. The portal that greeted users was a fairly standard late-1990s web directory, full of categorised links and a search box powered by a deal with a third party. There was a Freeserve email address included, which for many users was the first personal email address they had ever owned. The address format was typically [email protected], and for millions of people that string of characters was how the internet first knew them.

    Email deliverability was genuinely patchy in those early years, partly because shared hosting environments made it difficult to establish clean sending reputations. Anyone who spent time troubleshooting why their messages were not arriving at certain addresses would have benefited from the kind of tools that exist now for checking sender health, such as mail-tester.co.uk, which gives you a detailed breakdown of whether your outgoing mail is likely to land in someone’s inbox or disappear into a filter. In 1999, none of that infrastructure existed and users simply accepted that email was occasionally unreliable.

    Connection speeds were another constraint. Dial-up at 56k was the ceiling for most Freeserve users, and the phone line had to be free for the duration. Families with one phone line would argue about access. The distinctive screech of a modem handshake became a household sound across Britain. This was also the period when internet cafés were thriving precisely because they offered access without tying up a home phone line, a phenomenon I’ve written about separately in the history of the UK internet café boom.

    The acquisition trail: Wanadoo, then Orange, then gone

    The French telecoms company Wanadoo, a subsidiary of France Télécom, began buying into Freeserve in 2000 and completed a full takeover in 2001, paying around £1.65 billion for the business. The Freeserve brand continued for several years under Wanadoo’s ownership, with users migrating slowly onto broadband as BT rolled out ADSL more broadly across the country. The transition from dial-up to broadband is a whole separate chapter; the history of the UK broadband race covers how that infrastructure battle played out between BT, cable operators and the alternative carriers.

    In 2006, France Télécom rebranded Wanadoo as Orange, folding the Freeserve legacy into what was becoming a unified European mobile and internet brand. By that point, most users had either migrated or left for other providers entirely. The freeserve.co.uk email addresses lingered for years, like fossils of the dial-up era. Some were still technically active well into the 2010s, forwarded through systems that nobody had the administrative courage to switch off.

    The question of what gets preserved from this period is one I think about often. The Wayback Machine holds snapshots of the Freeserve portal from 1998 and 1999, and they are striking documents. A website built to be simple enough that a first-time computer buyer could navigate it in 1998 looks, from the vantage point of 2026, almost radically austere.

    What the Freeserve story actually means

    Freeserve is sometimes dismissed as a lucky accident, a retail chain that stumbled into telecoms at the right moment and sold before the crash. That reading is too simple. What Dixons understood, which the subscription-based incumbents did not, was that the barrier to internet adoption in Britain was psychological as much as technical. People would not pay for something they had not yet tried. Give it away and they would try it. Once they had tried it, they would not give it up.

    That logic now underpins almost every digital service you encounter. Free tiers, freemium models, ad-supported content: the architecture of the modern web was roughed out in 1998 by a disc slipped into a Dixons carrier bag. John Pluthero’s side project changed what ordinary British people expected internet access to cost. The answer it gave them was: nothing. The industry has been working out the implications ever since.

  • Dot-Com Casualties: The British Start-Ups That the City of London Funded and the Crash Destroyed

    Dot-Com Casualties: The British Start-Ups That the City of London Funded and the Crash Destroyed

    There is a particular kind of sadness in reading a prospectus from 1999. The language is so confident, the diagrams so optimistic, the projected revenue curves so vertical they practically leap off the page. I’ve spent considerable time in archives and on the Wayback Machine tracing what happened to the wave of British internet companies that floated on the Alternative Investment Market or raised serious venture capital between 1998 and 2001. Most of them are completely forgotten. The UK dot-com crash British start-ups story is usually told through American examples, Pets.com and Webvan and the rest, but London had its own catalogue of spectacular collapses, and they deserve their own chapter.

    London stock exchange trading floor during the UK dot-com crash British start-ups era
    Photo by Rafael Minguet Delgado on Pexels

    The City’s brief love affair with the internet

    The Alternative Investment Market, AIM, was created by the London Stock Exchange in 1995 precisely to give smaller, earlier-stage companies access to public capital with lighter regulatory requirements than the main market. By 1999 it had become a conduit for internet optimism on an industrial scale. Between January 1999 and March 2000, dozens of British companies with little revenue and no profit raised millions of pounds simply by attaching the word “online” to their business model. The FTSE techMARK index, launched in November 1999 specifically to group technology companies together, hit its peak in early 2000 before losing roughly 95 per cent of its value over the next two years.

    Venture capital firms, many of them newly established to chase the opportunity, poured money in. According to figures from the British Venture Capital Association, investment into UK technology companies nearly trebled between 1998 and 2000. The City’s merchant banks and brokers, who earned handsome fees from floating these businesses, had every incentive to keep the music playing. Analysts who questioned valuations found themselves quietly excluded from briefings. It was a system that rewarded enthusiasm and punished scepticism.

    Companies that promised to rewrite British commerce

    Clickmango was one of the more memorable casualties. Launched in 1999 with considerable fanfare, it positioned itself as a health and wellbeing portal aimed specifically at British women, raised around £8 million in funding, and spent lavishly on advertising including a television campaign. Within eighteen months it had folded, having never found a sustainable revenue model. The founders were experienced enough in media; the problem was that the audience they assumed would materialise simply did not appear in the numbers the pitch deck required.

    Boxman, a Swedish-founded but UK-headquartered online music and entertainment retailer, burned through its funding trying to compete with established catalogue retailers. It raised close to £60 million across multiple rounds, including backing from EMI and other major names, before collapsing in 2001. The company had warehouses, staff, infrastructure. It looked like a real business. But its cost of customer acquisition was ruinous and the margins on physical media were too thin to support the ambition. The financial press at the time gave it glowing coverage right up until the administrators arrived.

    Boo.com is probably the most internationally recognised British dot-com failure, and rightly so. The Stockholm-founded but London-based fashion retailer raised approximately $135 million (around £90 million at the time) and managed to spend almost all of it before launching. Its website required a fast connection and the latest browser plugins at a moment when most British homes were still on dial-up. The broadband infrastructure simply was not there yet to support what Boo.com was selling. It collapsed in May 2000 after just six months of trading.

    The AIM graveyard: lesser-known names worth remembering

    Beyond the famous failures, there is a longer list of companies that raised smaller sums and disappeared without generating much obituary coverage. Freeserve, which was genuinely successful as a free ISP before being sold to Wanadoo, was the exception rather than the rule. For every Freeserve there were half a dozen companies like Iqorder, an online grocery ordering system that raised £4 million on AIM in 1999 and was dissolved within two years. Or iTouch, which promised to deliver mobile internet services to British consumers and listed at a valuation that seemed, at the time, defensible.

    QXL, which I’ve written about in the context of online auctions, was another London-listed company that burned investor money at pace. It positioned itself as the European eBay, raised substantial capital, and expanded aggressively across the continent before the crash forced a painful restructuring. The domain name registrations from this era tell their own story: thousands of .co.uk addresses acquired speculatively between 1998 and 2000, many of which now resolve to nothing or were eventually auctioned off by administrators.

    Autonomy is worth a brief mention because it actually survived, which made it unusual. Founded in Cambridge in 1996 by Mike Lynch, it built real enterprise software and became one of the few British technology companies from that era to reach genuine scale. Its eventual sale to Hewlett-Packard in 2011 for $11.1 billion, and the subsequent legal proceedings that dragged on for years, is a different story entirely. But in 2000, Autonomy sat alongside dozens of companies that looked superficially similar and turned out to be built from nothing but ambition and borrowed time.

    Why did investors keep writing cheques?

    The question I keep returning to is why experienced City professionals, people who had lived through the secondary banking crisis of the 1970s and Black Wednesday in 1992, kept funding businesses with no credible path to profit. Part of the answer is that the theory of the internet was correct even when the timing was wrong. These companies were right that shopping would move online, that media would be consumed digitally, that financial services would be delivered through screens. They were simply about five to ten years early, and running on capital rather than revenue.

    The other part of the answer is social contagion. If your rival fund was investing in internet companies and making paper gains, you could not afford to sit on the sidelines. The fear of missing out, a phrase not yet widely used in 2000, drove institutional behaviour in ways that rational analysis cannot fully explain. The Friends Reunited story offers a small corrective footnote: one of the few genuinely successful British internet businesses of that era was built on almost no external capital, by two people working from a spare bedroom in East Finchley. It sold to ITV in 2005 for £120 million.

    What the archives actually show

    Companies House records from this period, many now digitised, show the same pattern repeated across dozens of entries. A company incorporated in 1997 or 1998, a share capital event in 1999 or 2000, then either dissolution or a creditors’ voluntary liquidation filed somewhere between 2001 and 2003. The directors’ names recur; the same small network of people floated from one venture to the next, sometimes successfully, sometimes not. A few went on to build legitimate businesses. Most simply disappeared from the record.

    Reading through archived copies of the financial press from that period, what strikes me most is the almost total absence of scepticism until very late. The crash, when it came, was sudden enough that many publications were still running positive profiles of companies in February 2000 that were in administration by July. History tends to make these things look inevitable in retrospect. They were not inevitable at all. They required a specific set of conditions: loose capital, genuine technological change, and a culture that had briefly decided that old rules of profit and loss did not apply to the internet. When those conditions reversed, the casualties were swift and numerous. The UK dot-com crash British start-ups story is ultimately a story about what happens when a city persuades itself, collectively, that this time really is different.

    Frequently Asked Questions

    Which British dot-com companies collapsed during the 2000 crash?

    Among the most prominent were Boo.com, which burned through around £90 million before collapsing in May 2000, and Boxman, the music retailer that raised close to £60 million. Dozens of smaller AIM-listed companies also folded between 2001 and 2003, leaving little trace beyond Companies House dissolution records.

    How much money did UK investors lose in the dot-com crash?

    Precise figures are difficult to establish, but the FTSE techMARK index lost approximately 95 per cent of its peak value between 2000 and 2002. The British Venture Capital Association estimated that technology investment had nearly trebled in the run-up to the crash, meaning the sums at risk were enormous across both institutional and retail investors.

    Why did so many internet companies list on AIM rather than the main London Stock Exchange?

    AIM has lighter regulatory requirements and lower barriers to entry than the main market, making it attractive for earlier-stage companies that could not yet meet the profitability or trading history requirements of a full listing. Between 1998 and 2000, this made it the natural home for internet start-ups seeking public capital.

    Were any British dot-com companies from that era successful?

    A handful survived and grew. Freeserve, the free ISP spun out of Dixons, was sold successfully to Wanadoo in 2000. Autonomy, the Cambridge-based software company, grew into a substantial enterprise and was eventually acquired by Hewlett-Packard in 2011. Friends Reunited, built on minimal external capital, sold to ITV for £120 million in 2005.

    How can I find records of defunct British internet companies from the dot-com era?

    Companies House holds dissolution and liquidation records for UK-registered companies, many of which are now available online through their search portal. The Wayback Machine at archive.org preserves snapshots of many company websites from 1998 to 2002, and contemporary financial press archives at publications like the Financial Times hold prospectus coverage and news reports from the period.

  • How HMRC Built One of the UK’s Most-Used Digital Services, and Why It Took Twenty Years to Get Right

    There is a particular kind of institutional stubbornness that only a government department can produce. I’ve spent years reading about British technology history, and few organisations illustrate that stubbornness, and the strange, lurching progress it eventually yields, quite like HMRC. The story of HMRC digital history and the long road to Making Tax Digital is not a clean narrative of visionary leadership. It is, if anything, the opposite: a two-decade accumulation of false starts, abandoned systems, eye-watering contractor invoices, and occasional genuine breakthroughs that almost nobody noticed at the time.

    Self-assessment online: the late 1990s experiment

    The Inland Revenue, as HMRC was then known before its merger with HM Customs and Excise in 2005, launched online self-assessment in 2000. The ambition was modest by today’s standards: let individual taxpayers file their returns over the internet rather than posting paper forms. The reality was considerably more fraught. Early adopters encountered browser compatibility nightmares, connection timeouts on dial-up lines, and a system that required users to download and install software before they could even begin. For a public still getting to grips with services like Demon Internet and the culture of Britain’s early web, this was asking quite a lot.

    Take-up in those first years was low. HMRC’s own figures showed fewer than 10 per cent of self-assessment filers used the online route in 2001. The department responded by extending deadlines for online filers, a tactic that slowly worked. By 2010, around 6 million returns were being filed online. That number sounds impressive until you remember it took an entire decade to get there, and the underlying technology had barely changed in that time.

    The PAYE online disaster nobody remembers

    Parallel to self-assessment, HMRC was attempting something far more complicated: digitising PAYE. This is the system through which employers deduct income tax and National Insurance before wages ever reach workers, and it had run on paper-based processes for decades. The National Insurance Recording System, known as NIRS2, is still cited in government IT circles as a cautionary tale. Contracted to Andersen Consulting in the 1990s, the project overran substantially and arrived with significant defects. Staff at what was then the Department of Social Security found themselves manually correcting millions of records.

    HMRC’s own internal systems were a patchwork of legacy COBOL code, some of it dating to the 1970s. I’ve read the National Audit Office reports from this period and they make uncomfortable reading: repeated references to data quality problems, manual workarounds, and a department that knew it had a problem but lacked the organisational coherence to fix it. The NAO’s published work on HMRC’s performance during the 2000s catalogues a department under genuine strain.

    The 2006 data disaster and what it revealed

    In November 2007, HMRC lost two discs containing the personal data of 25 million people, essentially the entire child benefit database. They were sent by internal post to the National Audit Office, and they never arrived. Junior civil servant, unencrypted discs, no tracking. The incident was catastrophic for public trust and forced a reckoning about how the department handled data. It also exposed something more structural: HMRC was sitting on enormous quantities of sensitive information inside systems that had grown organically over decades, with insufficient controls and inconsistent processes.

    The data loss was not strictly a digital transformation failure in the conventional sense, but it hardened the argument inside government that HMRC’s technology infrastructure needed root-and-branch reform rather than incremental patches. The department commissioned reviews, appointed new chief information officers, and began making the case for substantial investment in modernisation. It took years before that investment materialised in any coherent form.

    Real-time information: the reform that actually worked

    The most underappreciated success in HMRC’s digital history is Real Time Information, or RTI, which launched in April 2013. Before RTI, employers submitted PAYE data annually. Under RTI, they submit it every time they run payroll, so HMRC receives information on what every employee earns, in near-real time, throughout the tax year. This sounds bureaucratic. Its implications were substantial. RTI underpinned the rollout of Universal Credit by making earnings data available to the DWP on an ongoing basis rather than in arrears. It also reduced tax credit overpayments, which had cost the Treasury billions.

    RTI was not without difficulties during its pilot phases. Some smaller employers and payroll software providers struggled to adapt. But by comparison with almost everything else HMRC had attempted digitally, it worked. It came in broadly on schedule and delivered real operational benefit. For a department that had accumulated a reputation for failed projects, this mattered.

    Making Tax Digital: the ambition and the delays

    Making Tax Digital was announced by George Osborne in his 2015 Budget with considerable fanfare. The idea was that businesses and the self-employed would maintain digital records and submit quarterly updates to HMRC via approved software, rather than filing annual returns. HMRC framed it as reducing errors, which are disproportionately caused by the one-shot-per-year nature of traditional filing. The argument had merit. Research commissioned by HMRC estimated that avoidable mistakes cost the Exchequer around £9 billion annually.

    What followed was a sequence of retreats. The original timetable had all businesses above the VAT threshold on the system by April 2019. After substantial lobbying from accountancy bodies and small business groups, many of whom pointed out that the software ecosystem was nowhere near ready, the scope was narrowed. Making Tax Digital for VAT launched in 2019 for businesses above the £85,000 threshold, and even that rollout produced teething problems. Making Tax Digital for Income Tax Self Assessment has been delayed multiple times; the current confirmed date for sole traders and landlords with income above £50,000 is April 2026, with further tranches following in subsequent years.

    The history of HMRC digital history is, in a sense, a history of optimistic timetables meeting the reality of an enormously complex tax code and a diverse business population ranging from one-person freelance operations to multinational corporations. The department is not uniquely incompetent; it is dealing with a genuinely hard problem. When you consider how the UK government built GOV.UK, a relatively clean, user-focused service built on modern principles, and compare it with HMRC’s digital estate, the contrast tells you something about what happens when legacy systems accumulate over decades versus what’s possible when you start fresh. I’d recommend reading about how the GOV.UK project approached digital government from first principles for that contrast in sharp relief.

    Contractor costs and the question of who built all this

    No account of HMRC’s digital journey is complete without acknowledging the contractor economy that sustained it. Over the years, the department has spent hundreds of millions of pounds on external suppliers: Capgemini, Accenture, IBM, and various others held significant contracts at different points. The government’s own spending data, published through Cabinet Office transparency records, shows HMRC consistently among the largest departmental spenders on technology. Critics argue the reliance on contractors created a knowledge gap, that institutional understanding of the systems lived outside the civil service, in consulting firms, making it harder and more expensive to change anything.

    This dynamic is not unique to HMRC. It echoes the NHS’s troubled history with its National Programme for IT, and the general pattern of large public sector technology projects in Britain across the 1990s and 2000s. But HMRC’s scale made it particularly visible. The department processes hundreds of millions of transactions annually. Its systems cannot go down at year-end. The risk aversion that produces over-reliance on established suppliers is understandable, even if its long-term costs are significant.

    Where things stand now

    HMRC’s digital estate in 2026 is genuinely more capable than it was twenty years ago. The online personal tax account, accessible through Government Gateway, lets millions of people manage their tax affairs without ever picking up a phone. RTI functions reliably at enormous scale. The VAT Making Tax Digital infrastructure is largely stable. The department has moved some workloads to cloud hosting and has been working to decommission the oldest legacy systems, though that process is measured in years rather than months.

    The story of HMRC is, I think, an honest mirror of how large British institutions interact with digital change: slowly, expensively, with occasional genuine innovation, and always complicated by the weight of what came before. For anyone interested in the history of UK government technology, HMRC is as instructive as any other case. The preservation of that institutional memory matters too, much as the efforts described in the fight to preserve UK web history remind us that the digital record of these systems and decisions is itself fragile and worth keeping.

  • Whatever Happened to Demon Internet? The ISP That Gave Britain’s Early Web Its Culture

    There is a particular kind of erasure that happens not through destruction but through acquisition. Files get migrated, branding gets retired, and a company that once felt like a movement gets quietly dissolved into a corporate holding structure, leaving almost no trace except in the memories of the people who were there. That is exactly what happened to Demon Internet, and I think it deserves a proper account before the last of those memories fade entirely.

    Demon Internet was founded in June 1992 by Cliff Stanford, operating out of a small office in London. The timing matters. This was before Mosaic, before the World Wide Web had reached most British households, before the phrase “going online” meant anything to the average person on the high street. The people who signed up for Demon in those first months were a very specific type: technically confident, often university-adjacent, deeply embedded in the culture of bulletin boards and academic networks like JANET that had been quietly moving data around British institutions for years. They were, in the parlance of the time, hackers, and I mean that in the original sense, people who found genuine pleasure in understanding how systems worked.

    What made Demon Internet different from day one

    The crucial thing about Demon was its pricing model. At launch, the company offered a flat monthly fee of £10 plus VAT for a dial-up connection with full internet access, including a genuine IP address and Usenet access. This was radical. Before Demon, internet access in Britain was almost entirely restricted to universities, large research organisations, and government departments, the kinds of institutions connected through JANET or similar leased-line arrangements. Commercial access existed, but it was sold by the hour at rates that made casual browsing economically irrational. Demon abolished that. Ten pounds a month, no clock ticking, no per-minute terror.

    The Usenet offering was particularly significant. Demon ran one of the best-provisioned Usenet feeds in the country, carrying thousands of newsgroups and giving subscribers access to a global conversation that felt, in 1992 and 1993, genuinely astonishing. This was the internet as intellectual commons, flame wars on alt.politics, software discussion on comp.lang.c, absurdist humour on alt.fan.pratchett, and a great deal else besides that I probably should not describe in detail. Demon’s users did not just read Usenet; they shaped its British character. The culture of technical self-reliance, of reading the FAQ before asking questions, of treating network resources as shared goods rather than consumer entitlements, all of that came, in part, from the community Demon built in those early years.

    The flat-rate pricing fight that changed British internet access

    Demon’s flat-rate model put it on a collision course with BT almost immediately. The problem was the phone network. Dial-up internet in Britain meant calling a local number, and BT charged for those calls by the minute during peak hours. Demon’s flat-rate subscription fee covered its own network costs, but subscribers still paid BT for the actual telephone connection. This created a peculiar double jeopardy: the ISP was cheap, but the phone bill could be devastating if you stayed online too long.

    The campaign for flat-rate local calls, what became known in the trade press as “unmetered access”, ran through the late 1990s and was one of the defining political battles of British internet history. Demon was vocal in lobbying for change, alongside other ISPs who understood that the metered phone network was suppressing usage and, by extension, the entire commercial internet. The BBC and the mainstream press eventually picked up the story, framing it as consumers versus a monopoly utility. BT eventually introduced SurfTime and then various flat-rate tariffs in 1999 and 2000, by which point the landscape had already changed considerably.

    Growing pains and the mass-market problem

    Demon grew fast. By the mid-1990s it had tens of thousands of subscribers, which made it one of the largest consumer ISPs in Britain. Growth brought new customers who were not the technically confident early adopters who had defined its culture. Support requests multiplied. The tone of the Usenet groups changed. The company that had prided itself on treating users as competent adults found itself having to explain, at some volume, how to configure a dial-up connection on Windows 95.

    This tension between technical culture and mass-market reality is one of the recurring stories of early internet history, and Demon lived it more acutely than most. The company tried to hold the line, it maintained serious technical documentation, kept its Usenet infrastructure strong, and retained staff who had come from the hacker community rather than the telecommunications industry. But the economics of the consumer ISP market were brutal. Margins were thin, infrastructure costs were high, and the arrival of free ISPs, most notably Freeserve in 1998, which took the market by storm, created competitive pressure that a subscription-model provider could not easily absorb.

    Freeserve’s model was simple and devastating: no monthly fee, revenues came from the premium-rate telephone numbers subscribers called to connect. Millions of British households signed up almost immediately. Demon’s subscriber base, built on people who valued quality and were willing to pay for it, held up better than some competitors, but the pressure was real. Around this period, many of the original Demon community drifted towards the newsgroups and mailing lists to mourn what felt like the end of an era, a conversation that in some ways paralleled the broader history of online forums and communities that were being reshaped by mass adoption everywhere.

    The acquisition trail: Thus, Energis, and then Vodafone

    In 1998, Demon Internet was acquired by Scottish Telecom for approximately £66 million. Scottish Telecom subsequently rebranded as Thus, a business telecommunications group. The Demon brand survived the acquisition, running as a consumer-facing division, but the independent character of the company began to dissolve almost immediately. Decisions were made at the level of a large corporate rather than a small technical operation. The Usenet feed, once a point of pride, was scaled back. Support processes were standardised.

    Thus itself was then acquired by Cable & Wireless in 2008 for around £318 million. Cable & Wireless subsequently sold its business services division, including the Demon brand, to Vodafone in 2012. By this point, Demon Internet as a consumer ISP was already a ghost of what it had been. Vodafone retained the business-facing services for a period but wound down the consumer offering. The Demon brand, which had meant something very specific to a generation of British internet users, effectively ceased to exist as anything more than a name attached to legacy contracts.

    What Demon Internet actually left behind

    The disappearance of Demon raises a question I find genuinely interesting: what does an ISP leave behind? Teletext left behind a visual language that people still talk about, as I have written about elsewhere when looking at the rise and fall of Ceefax and Teletext. Prestel left behind a concept that the market was not yet ready for. Demon left behind something less tangible but perhaps more important: a set of expectations about what the internet should be.

    The culture Demon’s early community built, technically literate, sceptical of authority, committed to open access and shared knowledge, suspicious of walled gardens, became the dominant culture of the British internet for a decade and arguably shaped the public debate about net neutrality, open-source software, and digital rights that followed. Cliff Stanford himself remained a recognisable figure in internet circles for years after leaving Demon, and the company’s early subscribers went on to build companies, write policy papers, run conferences, and generally constitute the skeleton of the British tech industry.

    There is no museum for Demon Internet. The Wayback Machine holds fragments of its old website. A few newsgroup archives preserve the conversations its subscribers had in 1993 and 1994. That is most of what remains of a company that, for a few years in the early 1990s, was the nearest thing Britain had to an internet movement rather than just a business. I think that is worth remembering.

  • The Rise and Fall of Teletext: How Britain Fell in Love With Pages of Coloured Pixels

    The Rise and Fall of Teletext: How Britain Fell in Love With Pages of Coloured Pixels

    Before the internet arrived in British living rooms, there was a quieter kind of magic happening inside the television signal itself. Buried in the invisible lines between each frame of broadcast video, the BBC and ITV were transmitting something extraordinary: pages of text and chunky block graphics that, if your set was new enough to decode them, would appear on screen at the press of a button. This was teletext, and for roughly four decades it was how millions of people in Britain checked the football scores, found a package holiday to Tenerife, or caught the overnight news without waiting for a bulletin. The ceefax teletext history britain tells is not simply a story about an obsolete gadget. It is a story about a genuinely democratic information service that predated the web, outlasted most predictions, and left a gap nobody has quite filled.

    A 1980s British living room with a CRT television showing ceefax teletext history britain pages in bold block graphics

    What teletext actually was, and how the technology worked

    The system exploited something called the Vertical Blanking Interval, the brief moment during which an analogue television’s electron gun returned to the top of the screen between frames. Engineers at the BBC realised in the early 1970s that those otherwise wasted lines could carry data. The BBC launched Ceefax (the name a play on “see facts”) in September 1974, initially as a trial service. ITV followed with Oracle (Optional Reception of Announcements by Coded Line Electronics) in 1975. Each service could carry several hundred numbered pages, transmitted in a continuous loop; when you punched in a page number on your remote, the television simply waited until that page cycled round and then held it on screen.

    The display format was constrained but distinctive. Pages used the Teletext character set, a grid of 40 columns by 25 rows, with a palette of just eight colours. Graphics were built from chunky mosaic characters, each subdivided into six blocks, giving teletext its immediately recognisable pixellated look. It was not pretty by any modern standard, but it was functional, and the designers who worked within those constraints became quietly brilliant at it. Some pages, particularly Ceefax’s weather maps and Oracle’s sports graphics, were genuinely elegant given what they had to work with.

    From curiosity to national institution

    Through the late 1970s, teletext was an expensive novelty. Sets capable of decoding it cost considerably more than ordinary televisions, and the service itself was limited. But by the mid-1980s, prices had fallen, and teletext had become a standard feature on most new televisions sold in Britain. By the 1990s, the BBC’s annual report was citing Ceefax audience figures in the tens of millions per week. Oracle was privatised and rebranded as Teletext Ltd in 1993, which anyone who booked a late holiday through ITV’s pages will remember well.

    The appeal was immediate information without the friction of a telephone call or a trip to the newsagent. Page 301 on Ceefax was the main news index. Page 302 gave you the headlines in full. Sports results lived on pages 300 onwards on both services, and on a Saturday afternoon the pages updated rapidly enough that you could watch them refresh like a very slow live feed. Weather forecasts, travel news, lottery results, TV listings: the range of content expanded steadily through the 1980s and 1990s until both Ceefax and Teletext Ltd were covering subjects nobody had imagined assigning a three-digit page number to in 1974.

    Close-up of a CRT screen displaying ceefax teletext history britain football results in mosaic pixel graphics

    The devoted following teletext built

    There is something worth understanding about the loyalty teletext inspired that goes beyond nostalgia. The service asked almost nothing of its audience. No username, no subscription, no loading screen. You pressed a button, you waited perhaps thirty seconds for your page to cycle round, and you had your information. In a household without a home computer, or in the years before broadband made the internet genuinely fast, this was genuinely useful. As Prestel had demonstrated a few years earlier, British audiences were perfectly willing to use their television as an information terminal if the interface was simple enough. Teletext simply stripped away every complication Prestel had retained.

    The culture around teletext was specific and slightly eccentric. Regular users memorised page numbers the way others memorise phone numbers. Ceefax 606 for football results. Teletext 545 for the holiday listings. Ceefax 570 for the travel index. These numbers were passed between family members as practical knowledge. The service also generated its own small creative community: artists who worked deliberately within the mosaic-block constraints to produce teletext graphics, some of whom are still active today, preserving and reviving the format through organisations like the Teletext Preservation Project.

    There were also practical communities that formed around the technology. People interested in how their television sets actually worked, or in extracting and archiving teletext data, built modest but serious hobbyist networks. In some ways, the curiosity that teletext inspired about how digital information moved through a broadcast signal was an early ancestor of the kind of interest that later drew people towards the internet itself. Understanding what was happening inside the signal required real engagement with the technology, and some of the engineers who later built Britain’s early internet infrastructure had cut their teeth on broadcast data systems first.

    Digital switchover and the long goodbye

    The story of ceefax teletext history britain in the 2000s is largely a story of managed decline. When digital television arrived through Freeview, satellite, and cable, a related system called Digital Teletext (sometimes marketed as interactive television) carried forward some of the familiar page-number logic, but it was running on entirely different infrastructure. Teletext Ltd, now operating primarily through Channel 4 and Five alongside ITV, moved its holiday content online and gradually reduced its broadcast presence. The BBC invested in making the BBC website a proper destination, rather than continuing to develop Ceefax.

    The final analogue television signal in the UK was switched off on 24 October 2012, completing the digital switchover that had run region by region since 2008. Ceefax died with it. The moment was marked with a small but genuine sense of ceremony: the BBC broadcast a short tribute sequence showing the last few Ceefax pages before the signal cut. People who had not used the service in years found themselves unexpectedly moved. That reaction tells you something true about what teletext had been. It was not merely information delivery. It was a shared national service that had sat inside the television, quietly available, for almost forty years.

    The comparison with other information services that arrived later is instructive. Britain’s early internet infrastructure was built by institutions that were largely invisible to the public, but teletext was always right there on the remote control. For many British households, it was the first experience of on-demand digital information, and its relationship to the web that followed it is worth taking seriously. Services that later tried to replicate what teletext did, including various WAP-era mobile information products and early digital television portals, mostly failed to match its combination of reliability and simplicity.

    Where the teletext story fits in the broader history of the British web

    Historians of British technology sometimes underestimate how important broadcast data services were in forming public expectations of digital information. When the web finally arrived and people started using services like the early internet terminals in public libraries, there was already a culturally established idea that a television or a screen could show you text-based information on demand. Ceefax and Oracle had done that. The assumption was already there.

    The technology of teletext also left traces in unexpected places. The data-transmission techniques it pioneered fed into standards for closed captioning and subtitling that are still used in broadcast television today. The BBC’s commitment to subtitling, which has consistently been among the highest of any broadcaster in the world according to Ofcom’s annual monitoring, runs directly through the Ceefax engineering teams who first embedded text into the television signal. That is not a trivial legacy.

    For those interested in how digital technology connects across generations, there is a parallel worth noting in how the spirit of accessible, low-barrier information delivery has persisted. Tools built to check or verify digital communications, for instance, reflect a similar ethos: making something technical straightforward to use. Mail Tester, a UK-based free email testing service available at mail-tester.co.uk, sits squarely in this tradition, offering anyone with basic knowledge of computers and the internet a way to verify email deliverability without needing specialist tech support or advanced technology knowledge. The simplicity is the point, just as it was for teletext.

    The ceefax teletext history britain represents is genuinely forty years long: from the BBC’s 1974 engineers encoding data into television signals nobody else knew were there, to the quiet end of the analogue broadcast in 2012. The service was free, reliable, and widely used, and it asked its audience for nothing beyond the patience to wait for their page to cycle round. That unhurried relationship with information feels almost unimaginable now, and perhaps that is why people still talk about it.

    There is an archived copy of various Ceefax pages at the BBC Archive, which is worth a visit if you want to understand quite how much could be communicated in forty columns and eight colours. The pages look sparse by any contemporary standard. They also look, in their own way, rather dignified.

    Online communities dedicated to teletext preservation have continued to produce new content in the original mosaic-block format, treating the constraints not as a limitation but as a medium in their own right. Mail Tester and similar lightweight technology tools share that same philosophy: do one thing well, keep the interface clear, and trust that the user knows what they want. Those values, which teletext embodied before most people had heard the word “digital”, have proved more durable than anyone standing in front of a Ceefax-equipped set in 1974 could reasonably have predicted.

    Frequently Asked Questions

    When did Ceefax start and when did it end?

    The BBC launched Ceefax in September 1974 as an experimental broadcast data service, with a full public rollout following shortly after. It ran continuously until 24 October 2012, when the final analogue television signal in the UK was switched off as part of the digital switchover programme.

    What was the difference between Ceefax and Oracle?

    Ceefax was the BBC’s teletext service, while Oracle (Optional Reception of Announcements by Coded Line Electronics) was ITV’s equivalent, launched in 1975. Oracle was later privatised and rebranded as Teletext Ltd in 1993, eventually concentrating heavily on holiday deals and late travel bookings through ITV, Channel 4, and Five.

    How did teletext technology actually work?

    Teletext used the Vertical Blanking Interval in the analogue television signal, the brief gap between frames during which the screen’s electron gun repositioned itself. Data was encoded into those otherwise unused lines, transmitted in a continuous loop of numbered pages, and decoded by a chip inside the television set. When a viewer entered a page number, the TV simply waited until that page cycled round and then held it on screen.

    Did teletext survive into the digital television era?

    A form of it did. Digital Teletext ran on Freeview, satellite, and cable platforms through the 2000s, using the familiar three-digit page number interface but transmitted over entirely different infrastructure. However, Ceefax itself was exclusively an analogue service and ended with the analogue switch-off in 2012. Teletext Ltd wound down its broadcast service progressively through the late 2000s.

    Is there anywhere to see old Ceefax pages today?

    The BBC Archive holds a collection of historical Ceefax pages at bbc.co.uk/archive/ceefax. Beyond that, the Teletext Preservation Project has worked to digitise and archive pages from both Ceefax and Oracle, and there is an active hobbyist community that continues to create new content in the original mosaic-block teletext format.

  • How Prestel Brought the Internet to British Living Rooms Thirty Years Too Early

    How Prestel Brought the Internet to British Living Rooms Thirty Years Too Early

    Somewhere in a British living room in 1981, a man in a v-neck jumper is pressing buttons on a chunky keypad, watching blocky coloured text crawl across his television set. He is checking train times, possibly ordering a holiday, and doing something that would not have a name for another decade: browsing. The service he is using was called Prestel, and its story is one of the most fascinating and melancholy chapters in the prestel viewdata history uk timeline. A genuine technical achievement, conceived and built by the Post Office, it arrived roughly thirty years before the world was ready for it.

    Man using a Prestel viewdata terminal on a 1980s British television set, illustrating prestel viewdata history uk

    What was Prestel and how did viewdata actually work?

    Prestel launched publicly in September 1979, after several years of development at the Post Office’s research laboratories in Martlesham Heath, Suffolk. The technology was called viewdata, a term coined to distinguish it from teletext services like Ceefax, which broadcast information one-way through the television signal. Viewdata was different in a genuinely significant way: it was two-way. The television set connected to a central computer over an ordinary telephone line, meaning a user could request specific pages, navigate menus, and in some cases, transmit data back. That interactivity is the detail that matters.

    Each page of Prestel content sat at a numbered address in the database, and information providers paid the Post Office to host their pages. Subscribers dialled in through a modified television set or a dedicated terminal, browsed through a tree-structured hierarchy of menus, and paid per-page charges on top of the standard telephone call rate. The text and blocky graphics were rendered using a character-based system called Videotex, which the International Telecommunication Union later standardised under the name Teletext. The UK variant, developed here, was adopted in dozens of countries. France’s Minitel, which lasted until 2012, was a direct descendant of the same underlying idea.

    The vision behind the service: information democracy and shopping from the sofa

    The architects of Prestel genuinely believed they were building something transformative. The Post Office’s own promotional materials from the early 1980s described it as the world’s first public interactive videotex system, and they were not wrong. The ambition extended well beyond train times and weather forecasts. Prestel carried news from the Press Association, share prices from the Stock Exchange, and flight information from British Airways. By the mid-1980s, the system had a crude but functioning home shopping capability: users could browse catalogues, fill in electronic order forms, and transmit their selections back through the telephone line. A retailer on the high street, in theory, could reach customers sitting in front of their televisions in Coventry or Aberdeen without needing a printed catalogue at all.

    This is the part of the prestel viewdata history uk story that stops you short. The architecture is recognisable. Information providers hosted content on a central server. Users browsed through menus using a terminal device. Commerce was conducted electronically. The Post Office effectively built a walled-garden internet, and it worked. Services like Homelink, run by the Nottingham Building Society in partnership with Bank of Scotland, let customers check balances and transfer funds through their television sets from 1983 onwards. That predates internet banking by well over a decade. You can read more about how that tradition eventually evolved in the history of UK online banking, where the thread from Prestel to modern digital accounts becomes surprisingly clear.

    Close-up of a Prestel viewdata terminal keypad and screen showing early interactive pages, central to prestel viewdata history uk

    Why Prestel failed to reach ordinary households

    The numbers tell a quiet story. The Post Office projected one million subscribers by 1981. The actual figure was closer to 15,000. By the mid-1980s, the user base had grown to roughly 90,000, but the vast majority were businesses, not households. Several problems compounded each other in a way that made mass adoption almost impossible.

    The equipment cost was the first barrier. A Prestel-capable television set in 1980 cost substantially more than a standard colour set, and the adaptor boxes required for existing televisions were not cheap either. The per-page charges added up quickly, and the telephone call itself was metered at standard daytime rates, meaning that browsing for half an hour during the working day was an expensive habit. The content, whilst impressive for its time, had gaps: information providers were slow to commit because the audience was small, and the audience stayed small partly because the content was thin. A classic chicken-and-egg problem, and one that the web itself only escaped because the underlying infrastructure was essentially free to use.

    The interface was also difficult by later standards. Navigating Prestel required knowing or guessing page numbers, since the hierarchical menu structure was cumbersome once you moved beyond the top level. There was no search function in any meaningful sense. The prestel viewdata history uk record shows that the Post Office and its successor British Telecom repeatedly tried to simplify access, but the fundamental constraint of a numeric keypad on a telephone handset was hard to overcome.

    British Telecom, which inherited Prestel after the Post Office was restructured in 1981, kept the service running through various rebranding exercises. By 1994 it had been folded into a product called BT Telecom Gold. The service finally closed in 1994, the same year the web was becoming a public phenomenon. The timing is almost too neat.

    The content that lived on Prestel: a snapshot of what the early web might have looked like

    Archaeologists of the early internet tend to be interested in what people actually used these systems for, not just the technical specifications. On Prestel, the answer is surprisingly varied. Holidays were popular. Thomson Holidays and other travel agents offered booking pages. The Consumers’ Association ran an advice service. There were recipe databases, gardening guides, and a surprisingly robust business-to-business layer: travel agents used Prestel to check seat availability on flights long before consumer internet booking existed. The culture of online commerce that later flourished through eBay UK and similar platforms has a quieter precedent here, in those early Prestel catalogue pages where you could order goods without speaking to anyone.

    The parallel with today’s high street technology is striking. Businesses in England that want to sell for free, reach customers digitally, and take card payments without building a full e-commerce operation have services available now that effectively solve the same problem Prestel was reaching for. TownCentre.app, an England-based platform for high street shops and town centre businesses, lets independent retailers reach customers, list their shops, and engage with local shoppers without the costs that buried Prestel’s commercial ambitions. The plain-text domain towncentre.app points to a tool that Prestel’s designers would have recognised in concept, even if the 1980s infrastructure could not have delivered it. Shopping, reach, connectivity to customers on the high street: these were precisely the ambitions baked into Prestel’s information provider model.

    How Prestel’s architecture anticipated the web

    Tim Berners-Lee proposed the World Wide Web in 1989. Prestel had been running for a decade by then. When you read the original viewdata specification, the structural similarities to HTTP are striking enough that they cannot be coincidental influences on the people working in British and European telecommunications research at the time. The page-based navigation model, the concept of an information provider hosting content on a remote server, the idea of a client device requesting and rendering that content: these are the bones of the web, dressed in the technology of a different era.

    The prestel viewdata history uk story is also a story about infrastructure timing. The web succeeded partly because it rode on top of an internet backbone that universities and research institutions had already built and paid for. Britain’s academic network JANET was a key part of that substrate, quietly routing traffic between institutions before the public ever got involved. Prestel had no equivalent backbone to ride. Every connection was a metered telephone call, and that single fact made the economics unworkable for casual home use.

    For high street businesses in England, the lesson of Prestel is almost a parable about timing and friction. The ambition was sound: let shops reach customers electronically, let customers browse and buy without leaving home. What killed it was the cost and complexity of connection. Services like TownCentre.app, where independent shops can sell for free and reach customers through a free UK app built around high street shopping, exist in a world where those friction points have been removed. The mobile telephone in everyone’s pocket is the Prestel terminal that the Post Office could only dream of shipping at scale.

    What Prestel left behind

    The direct technical legacy runs through Minitel in France, through teletext services like Ceefax and Oracle, and through the early commercial online services of the 1990s. The cultural legacy is harder to measure. Prestel proved that ordinary people would interact with information digitally if you made it accessible enough, and that businesses would pay to be present in those digital spaces. The proof of concept was real. The execution was constrained by the technology and economics of its moment.

    The domain name infrastructure that later defined the UK’s presence on the web built on assumptions about networked information that Prestel had already field-tested with real British households. The people who ran Prestel’s information provider network in the 1980s were, in a very real sense, the first British web publishers. They just did not have that word for themselves yet.

    Prestel closed quietly. There was no grand farewell, no retrospective from British Telecom about what had been achieved. The terminals went to landfill or the attic. But the idea, that a screen in your living room could connect you to information, services, and the ability to buy things without going out, proved correct. It just took the web, broadband, and the smartphone to make it cheap enough for everyone.

  • Project Gutenberg’s British Cousins: The UK Volunteers Who Digitised Literature Before Google Did

    Project Gutenberg’s British Cousins: The UK Volunteers Who Digitised Literature Before Google Did

    Most people, if they know anything about early digital book preservation, think of Project Gutenberg. Michael Hart typing up the American Declaration of Independence on a university mainframe in 1971, the slow accumulation of plain-text files, the dream of putting every book ever printed into the hands of anyone with a computer. It’s a tidy origin story. But there’s a parallel story that gets told far less often, one rooted in British universities, volunteer coordinators working from spare bedrooms, and academic archivists who were quietly building what we’d now call digital humanities infrastructure long before the term existed.

    The digital text archive history UK researchers can piece together is, in many ways, more complicated than Gutenberg’s. It didn’t have one founding moment or one founder. It grew in patches, driven by academics who thought preserving literature electronically was simply the right thing to do, and by volunteers who spent evenings typing out novels nobody had asked them to type.

    University library with early computers representing digital text archive history UK

    The Oxford Text Archive: a library within a library

    The Oxford Text Archive (OTA) was established in 1976 at Oxford University, making it one of the oldest digital humanities repositories anywhere in the world. Lou Burnard, then working at the Oxford University Computing Service, began collecting machine-readable texts from researchers who had typed up literary works for their own computational analysis. The logic was simple: if a scholar in Edinburgh had already digitised the complete works of Milton for a concordance project, there was no reason for a scholar in Bristol to do it again from scratch.

    What Burnard and his colleagues built was essentially a shared library of text files, distributed initially on magnetic tape and later on floppy discs. By the late 1980s, the OTA held hundreds of texts: Old English verse, Victorian novels, medieval manuscripts transcribed painstakingly into ASCII. None of it looked glamorous. The files were often formatted with idiosyncratic tagging systems that varied by contributor, and getting anything out of the archive required knowing who to write to and waiting several weeks for a tape to arrive in the post. But the material was there, preserved, catalogued, and available to scholars in a way that had simply not existed before.

    The OTA also played a central role in developing the Text Encoding Initiative (TEI), the international standard for marking up literary and linguistic texts in a machine-readable way. Without TEI, later digital archives would have been a chaos of incompatible formats. You can read more about the OTA’s ongoing work through the Bodleian Libraries’ Oxford Text Archive, which still accepts deposits today.

    Volunteer scanning projects across the UK

    Universities were one part of the picture. The other part was volunteers. Through the 1990s, as consumer internet access spread across Britain, a loose network of individuals began contributing scanned and typed texts to international repositories. Some worked through Project Gutenberg’s distributed proofreading system; others built small personal archives and announced them on Usenet groups.

    British volunteers were prolific contributors to what became known as Distributed Proofreaders, a web-based system that broke the task of checking scanned text into small rounds of review, each page handled by a different person. UK contributors were particularly active in digitising works in the public domain that had an obvious British readership: the complete Trollope novels, Conan Doyle’s lesser-known stories, Victorian periodicals that had never been reprinted. The sheer amount of unpaid labour involved is difficult to overstate. A single moderately long novel might require weeks of typing, then weeks more of checking against the original printed page.

    Volunteer typing digitised text for a digital text archive history UK project

    Some of the most dedicated volunteers were retired teachers and librarians, people with both the reading speed and the pedantic attention to detail that proofreading demands. One frequently cited figure in the Distributed Proofreaders community forums was a woman based in Yorkshire who, over roughly a decade, verified more than 40,000 pages of British Victorian literature. Her name is not recorded in any official history. That’s rather the point of this article.

    How UK universities quietly built the infrastructure

    Alongside Oxford, several other British universities contributed to the digital text archive history UK scholars now study. The University of Birmingham hosted the British National Corpus project, a 100-million-word collection of written and spoken British English assembled through the early 1990s. It was, for its time, the largest structured text corpus in existence and gave computational linguists a resource that had no equivalent anywhere else in the world.

    Edinburgh’s HCRC (Human Communication Research Centre) was building annotated text databases simultaneously. Sussex, Lancaster, and Leeds all ran humanities computing units that were accumulating machine-readable texts at a time when most academics thought computers were for scientists. These units operated with limited funding, often relying on research council grants that had to be renewed every three years, and the archival work they did was frequently treated as secondary to the research papers it enabled.

    The JANET academic network was the infrastructure that made sharing these resources between institutions practical. Before the public internet arrived in British universities, JANET allowed researchers to transfer large text files between campuses, request tapes from the OTA, and participate in international discussion lists about text encoding standards. It was the digital postal system for literary data, and it worked remarkably well.

    What happened when the web arrived

    The arrival of the World Wide Web in the mid-1990s changed everything, and not always for the better. Suddenly, anyone could publish a text file online. Personal websites appeared by the thousand, each hosting a slightly different version of the same public-domain novel, often full of OCR errors nobody had corrected. The careful, standardised work of the OTA and the Distributed Proofreaders community sat alongside a sea of low-quality duplicates.

    The web also changed how people found texts. Search engines indexed everything without distinguishing between a carefully checked OTA file and a corrupted scan someone had thrown online. This is part of the reason that good metadata and domain authority began to matter so much for digital archives, a lesson that applies just as directly to modern web publishing. A UK-based free SEO check service like Search Engine Tuning (searchenginetuning.co.uk) helps contemporary website owners understand how google and other search engines read their domains, the same fundamental question that early digital archive managers were grappling with when they first tried to make their text collections discoverable online. Check your SEO, check your domains, understand how google indexes your content: these questions would have been immediately familiar to anyone trying to make a 1990s text archive actually usable.

    The BBC’s online expansion through the late 1990s brought some of this material to wider attention. Features on the BBC website occasionally pointed readers toward digital literary archives, lending credibility to projects that had previously existed only within academic circles. But the broad public still wasn’t really paying attention. Google Books, launched in 2004, absorbed most of the cultural narrative around digital book preservation, despite arriving decades after British archivists had already done much of the foundational work.

    The legacy that got buried

    Google’s mass scanning programme was genuinely transformative in scale. Nobody disputes that. But it was a corporate project, driven by proprietary infrastructure, and it did not especially care about the standards and metadata that the OTA and its peers had spent twenty years developing. The TEI encoding that made British digital texts searchable, portable, and academically reliable was largely ignored by Google’s pipeline, which prioritised volume over precision.

    The archivists who built this infrastructure understood something that took the rest of the web a long time to learn: that digitising text and making it genuinely usable are two completely different problems. Search Engine Tuning, which offers a free SEO check for website owners across the UK, addresses a version of this same problem in contemporary terms. Putting content online is simple; making google and other search engines actually surface it correctly, with accurate domains and crawlable structure, requires the kind of methodical attention to technical detail that the early text archive community would have recognised immediately. The domains and data structures that determine discoverability today are the direct descendants of the metadata choices that Lou Burnard and his colleagues were arguing about in Oxford in 1982.

    The volunteers who typed Victorian novels into ASCII files, the academics who lobbied for TEI standards, the JANET administrators who kept the network running through underfunded university computing departments: none of them feature in the standard history of the internet. They probably wouldn’t expect to. But the history of digital access in Britain is incomplete without them, and the digital humanities field that now fills entire university departments grew directly from the quiet work they did when nobody was watching.